Home

The scorecard. Failures included.

G-Code Lite 0.10.0 on one iPad Air with M2, 22 to 25 October 2026. Six batches of AI-built* work in the order they ran: each scored run, every round that failed before it, and what was fixed in between.

  • 37/37tasks passed in the runs that were scored
  • 22fixes to G-Code Lite along the way

* Tasks built and components tested using the Claude API.

Six batches, in the order they ran.

One square is one task in one run.

Six test batches with their runs, scored result, scored cost and the fixes they led to
WhenBatchRunsScoredCostApp fixes
Twenty small appsOne page each, on a named npm package. Round 1: 9 of 20 passed. Round 2: 17 of 20. Round 3: 20 of 20. 20/20 $0.70 8
Four five-page sitesA gym, a shipping line, a data centre, a coffee estate. Scored run: 4 of 4 passed. 4/4 $22.94 8
Project PRIDEOne ten-page site, refined over seven rounds. One project, passed. 10/10 pages $29.13 0
Four runtime tasksPython, Node.js, C/C++ and shell in the app's terminal. First run: 3 of 4 passed. R3 ran again and passed. 4/4 $0.0139 0
Stress: larger projectsReact, Python, multi-file C++ and Node.js, each with its own tests. Round 1: 2 of 4 passed. Round 2: the two that failed ran again and passed. 4/4 $0.15 2
Stress, doubledTwice the packages, files and checks. All four in one run. Round 1: 2 of 4 passed. Round 2: 3 of 4. Round 3: 4 of 4. 4/4 $0.66 4

The log.

What ran, what broke, and what changed in the app before the next run.

Twenty small apps. Three rounds.

Single-page apps, AI-built* on a named npm package each, $5 budget each. A round passed only if all twenty built in one run.

Round Pomodoro Tip Calculator Todo List Unit Converter BMI Calculator Coffee Landing Portfolio Countdown Solar Quiz Color Palette Word Counter Weather Cards Pricing Table FAQ Accordion Recipe Card Stopwatch Memory Game Quote Generator RSVP Form Habit Tracker
Round 1 9/20 $0.57 Pomodoro, canvas-confetti: passed Tip Calculator, currency.js: passed Todo List, @formkit/auto-animate: failed, hit the agent's step limit Unit Converter, convert-units: failed, hit the output limit BMI Calculator, chart.js: passed Coffee Landing, animejs: failed, lost the network Portfolio, @formkit/auto-animate: failed, hit the agent's step limit Countdown, dayjs: passed Solar Quiz, canvas-confetti: passed Color Palette, chroma-js: failed, preview too slow for the test Word Counter, words-count: failed, not run, the test could not open it Weather Cards, chart.js: passed Pricing Table, animejs: failed, hit the agent's step limit FAQ Accordion, fuse.js: failed, hit the agent's step limit Recipe Card, fraction.js: failed, hit the agent's step limit Stopwatch, @formkit/auto-animate: passed Memory Game, canvas-confetti: passed Quote Generator, animejs: failed, hit the agent's step limit RSVP Form, zod: failed, hit the output limit Habit Tracker, dayjs: passed
Round 2 17/20 $0.73 Pomodoro, canvas-confetti: passed Tip Calculator, currency.js: passed Todo List, @formkit/auto-animate: passed Unit Converter, convert-units: failed, runtime error from Node's global BMI Calculator, chart.js: passed Coffee Landing, animejs: passed Portfolio, @formkit/auto-animate: passed Countdown, dayjs: passed Solar Quiz, canvas-confetti: passed Color Palette, chroma-js: passed Word Counter, words-count: passed Weather Cards, chart.js: passed Pricing Table, animejs: failed, cut off at request 10 FAQ Accordion, fuse.js: failed, lost the network Recipe Card, fraction.js: passed Stopwatch, @formkit/auto-animate: passed Memory Game, canvas-confetti: passed Quote Generator, animejs: passed RSVP Form, zod: passed Habit Tracker, dayjs: passed
Round 3 20/20 $0.70 Pomodoro, canvas-confetti: passed, $0.0252 in 3:52 min Tip Calculator, currency.js: passed, $0.0381 in 3:57 min Todo List, @formkit/auto-animate: passed, $0.0263 in 4:20 min Unit Converter, convert-units: passed, $0.0587 in 4:55 min BMI Calculator, chart.js: passed, $0.0439 in 5:43 min Coffee Landing, animejs: passed, $0.0379 in 5:00 min Portfolio, @formkit/auto-animate: passed, $0.0397 in 4:53 min Countdown, dayjs: passed, $0.0218 in 3:43 min Solar Quiz, canvas-confetti: passed, $0.0331 in 4:33 min Color Palette, chroma-js: passed, $0.0363 in 4:56 min Word Counter, words-count: passed, $0.0287 in 4:30 min Weather Cards, chart.js: passed, $0.0347 in 4:58 min Pricing Table, animejs: passed, $0.0408 in 5:01 min FAQ Accordion, fuse.js: passed, $0.0261 in 4:43 min Recipe Card, fraction.js: passed, $0.0664 in 5:41 min Stopwatch, @formkit/auto-animate: passed, $0.0251 in 4:47 min Memory Game, canvas-confetti: passed, $0.0243 in 3:58 min Quote Generator, animejs: passed, $0.0258 in 5:10 min RSVP Form, zod: passed, $0.0445 in 6:09 min Habit Tracker, dayjs: passed, $0.0258 in 5:26 min
  • Round 1 · $0.5690 Six hit the agent's step limit and two its output limit; one lost the network, one previewed too slowly, one never ran.
  • Round 2 · $0.7324 A runtime error from Node's global, a cut-off at request 10 that the round's own fix brought in, a lost network.
  • Round 3 · $0.7032 All twenty in one run: 98 minutes, $0.035 an app.
Eight fixes between the rounds
A package guide
npm_install now tells the AI where the package is, how to import it, and the start of its types and README examples.
64K output
The agent's output cap went from 32K to 64K, and large changes go in several steps.
Shared limits
The agent and its build check share one set of request limits. This fixed round two's cut-off.
Automatic build check
Files the AI stages without passing build_check are checked on the iPad anyway.
A faster local builder
A chroma-js page went from 78.9 s to 4.9 s to build, on the simulator.
Node's global
Browser builds map global to globalThis, so Node-style packages run.
Clearer console
The preview console names blocked eval and inline code correctly.
Clearer errors
A rejected key no longer gets a message meant for another provider.
Four five-page sites.

Five pages each on a $20 budget, AI-built* and then looked at and refined page by page. Each used about a quarter of its budget.

The four five-page sites in their scored run
SiteCostTimeLooks / editsPackage
Basalt fitness$5.774337 min11 / 22dayjs 1.11.23
Norrhavn Line shipping$6.170037 min10 / 36chart.js 4.6.1
Tarnwell data centre$5.231428 min*10 / 37animejs 4.5.0
Cerro Nublado coffee$5.763037.5 min9 / 29currency.js 2.0.4
Four sites$22.94
Eight fixes before the scored run
Every page builds
Only the entry page of a multi-page site used to be built; pages with npm imports failed in the preview.
Room for sites
60 requests, 160 tool calls and 128K output per reply.
preview_screenshot
A new tool: the AI sees its own pages in landscape, portrait or phone width.
edit_file
A new tool: refinements replace only the text that changes, instead of whole files.
Prompt caching
Resent input had been about 75% of each site's cost.
No more freezes
A full backup ran on every staged change. A whole test task went from 46 s to 15 s.
Patient streaming
A streamed reply may pause for up to 5 minutes, not 60 seconds.
mount
Choosing a folder in Files no longer prints "mount: cancelled".
Notes, and what wasn't counted

* Agent time only: Tarnwell's test stopped at the contact form, and a second pass that sent nothing opened all five pages. Two sites set text over a busy illustration in one orientation: Basalt's program page in portrait, Norrhavn's home page in landscape.

Not counted: a first run before the AI could see its pages, which drew flat line art ($5.95, $5.67 and $8.26 for three sites, then paused), and attempts stopped by the problems fixed above, including $15.39 at a budget handoff and $11.31 when one conversation grew too large.

Project PRIDE. Seven rounds.

One ten-page research-lab site, AI-built* on a $45 budget. All ten pages build and open with an empty console.

  1. Round 1 the brief$11.39
  2. Round 2 every page again$2.95
  3. Round 3 hero, home, phone$4.26
  4. Round 4 search, charts, form$3.38
  5. Round 5 portrait; HTTP 502$2.57 + $8.07 held
  6. Round 6 finish round 5$3.10
  7. Round 7 again; usage limit$1.48

$29.13 settled over 154 requests and 101 minutes of agent time. Both stops came from the provider, so no app fixes came out of this batch.

The held $8.07 and the two stops

Round 5 ended on an HTTP 502 from Anthropic after six files had been staged and applied; round 6 finished that pass in the same project. The request cut off by the 502 still holds $8.07 in the app's budget. Its real charge, at most $8.07, is in the Anthropic Console, not here.

Round 7 was refused with HTTP 400 at its fourth request, almost certainly by the account's monthly usage limit. The $7.80 left was below the $8 a further round needs.

Per round: 53, 7, 11, 11, 8, 8 and 2 minutes; 35, 6, 8, 13, 6, 6 and 0 files applied. Over the seven rounds: 90+ looks and 123+ edits.

Four runtime tasks.

Python, Node.js, C/C++ and shell, AI-built* on $1 each, then run in the app's own terminal and checked line by line.

The four runtime tasks
TaskChecked in the terminalResultCostTime
R1 Python sales reportRevenue per region and the 692.00 total; report.jsonPassed$0.00502:00
R2 Node.js task plannernpm start prints the sorted plan and NEXT; summary.jsonPassed$0.00261:43
R3 C and C++15 primes, a matrix product, std::sort, a mean of 18.00Passed, second run$0.00401:57
R4 Terminal inventoryLine counts 3, 5, 4 and four TODO lines from grep -rnPassed$0.00232:23
R3's first run, and an attempt the account refused

R3's first run printed the matrix as [[19, 22], [43, 50]] where the check wanted 19 22 43 50. The program was right; the brief never said how to print it. The brief was fixed and only R3 ran again. The first run's $0.0027 is not counted.

An attempt earlier that morning was refused at the first request because the account had hit its usage limit: $0.

Stress: bigger projects, more packages.

An outside review said the real test is complex projects with large dependencies. Four AI-built* projects, each with its own tests, on $23 for the batch.

The first stress batch, task by task and round by round
TaskRound 1Round 2
S1 React budget app16 npm packages, four pages Failed $0.0049The AI asked for 16 installs in one reply; the app took only 8 tool calls per reply. Passed $0.0945 · 9:33
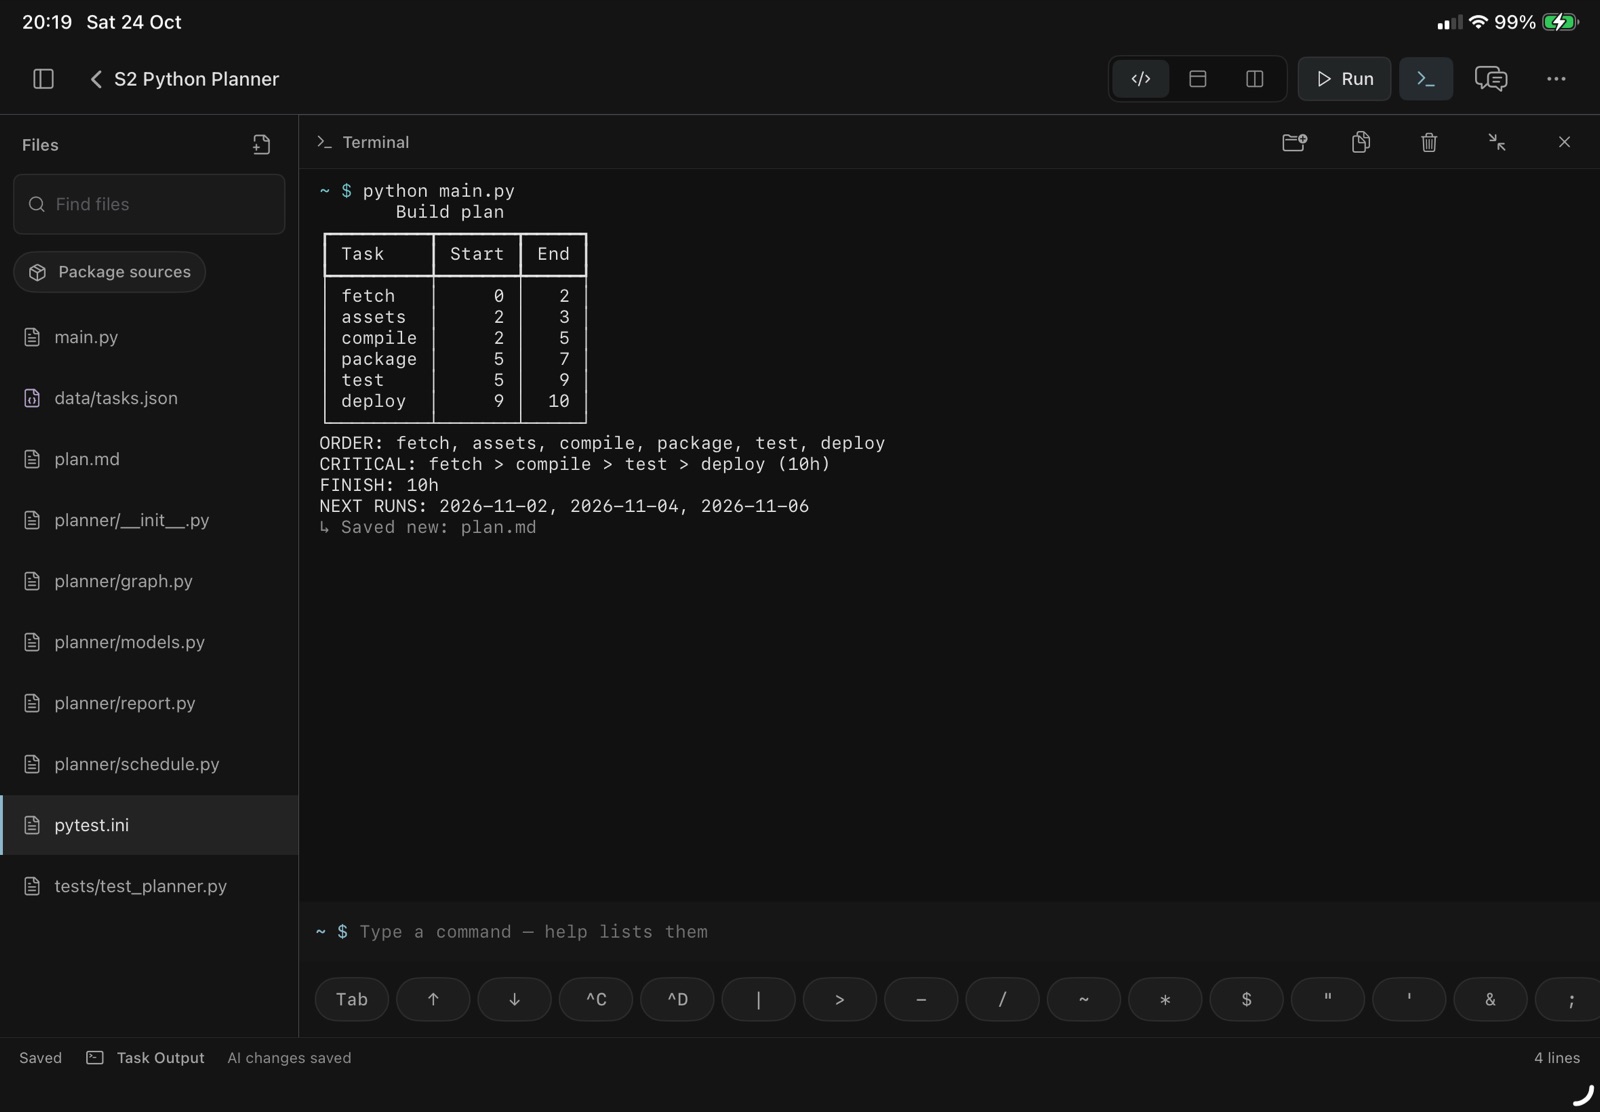
S2 Python build planner6 PyPI packages and pytest Passed $0.0123 · 4:01 Not run again
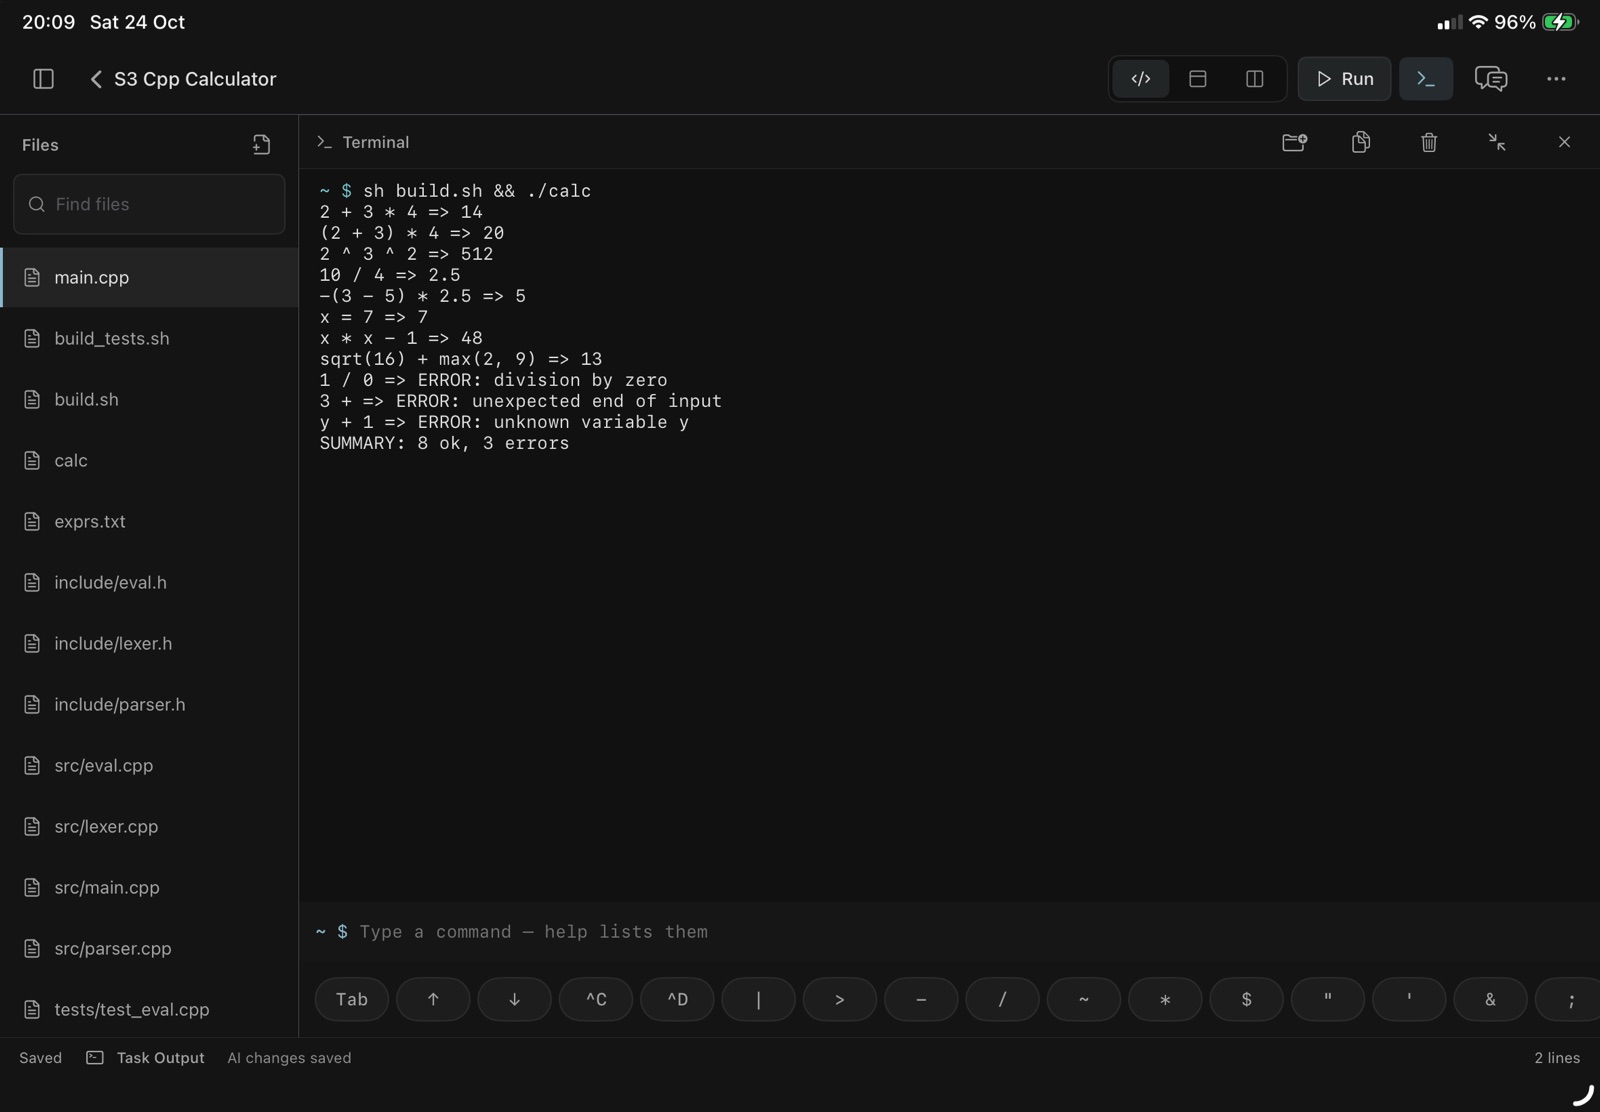
S3 C++ calculator7 sources, 3 headers, no exceptions Passed $0.0211 · 4:22 Not run again
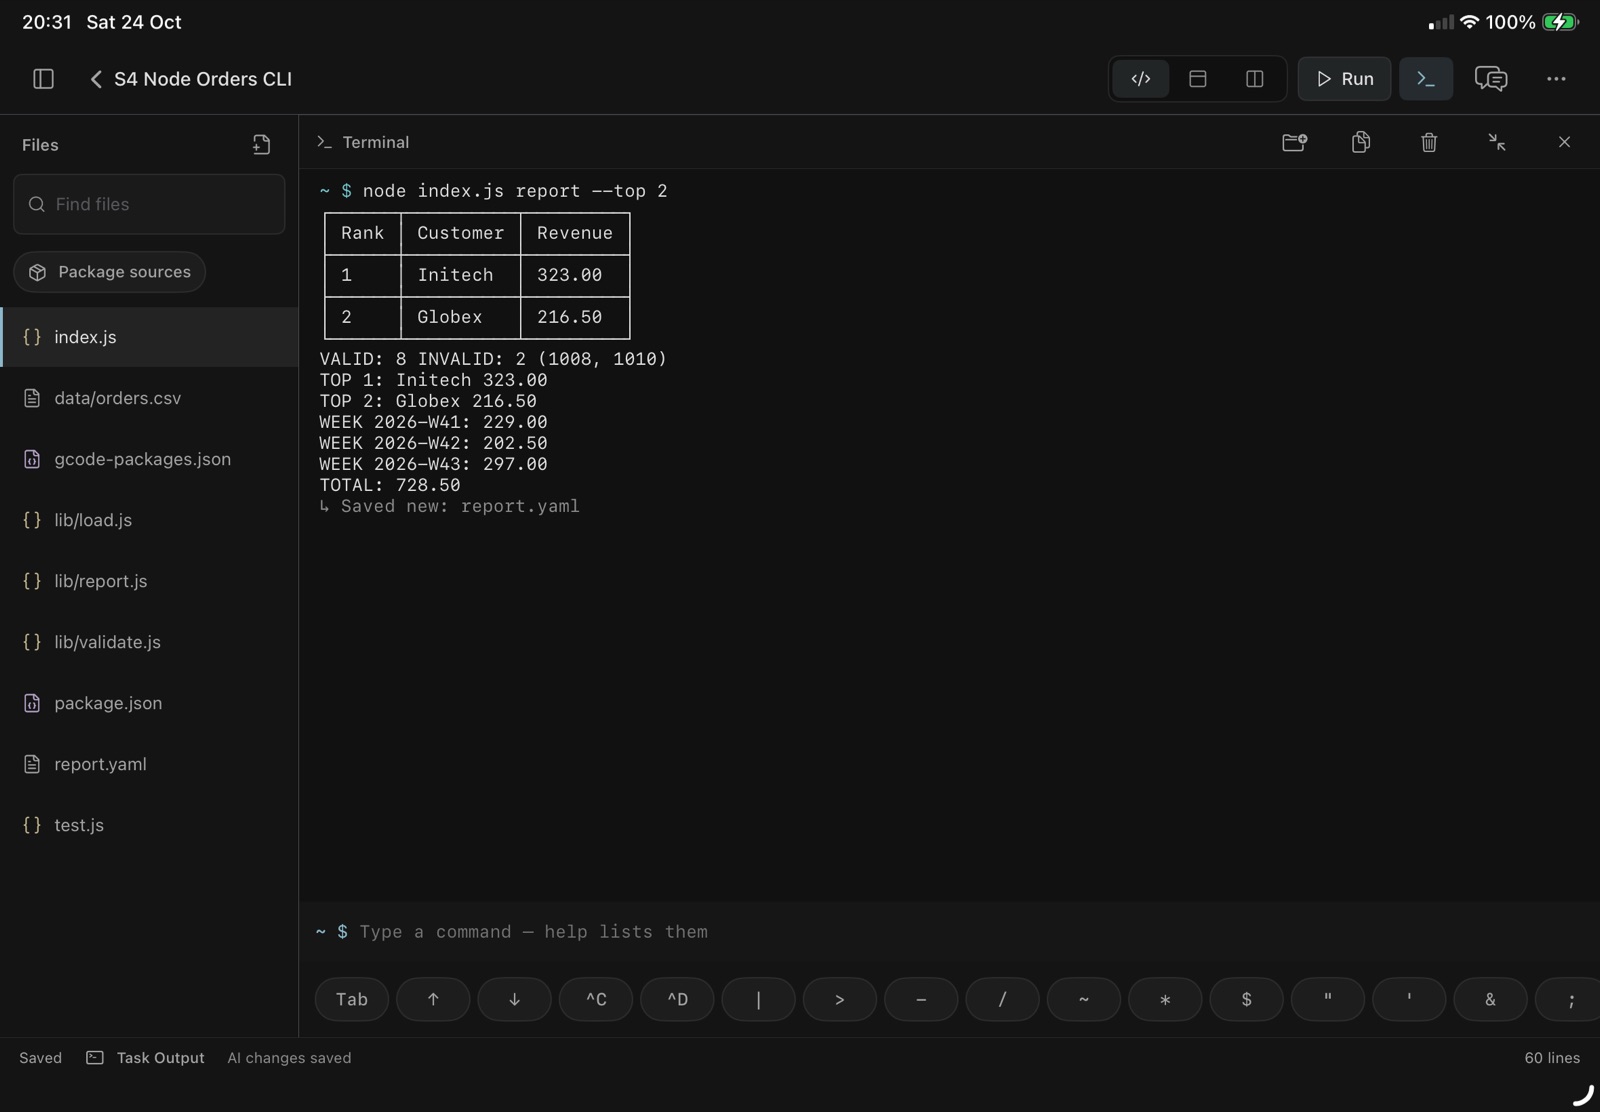
S4 Node.js order report7 npm packages Failed $0.0224Old package copies piled up past the file limit, reported as a 128 MB problem. Passed $0.0230 · 5:11
Per round2/4 · $0.06072/2 · $0.1175

Scored: S2 and S3 from round 1, S1 and S4 from round 2, $0.1509 in all.

Two fixes, in build 24
One copy of the packages
Every install used to keep the old copy of every package. Only the current set is kept now, and too many files gets its own message.
32 tool calls per reply
Up from 8, so the AI can ask for every install at once.
What each task was checked against
S1
Every page through the navigation, search, form validation, adding a row, Markdown, the console. 16 packages, 22 with their dependencies.
S2
Run order, a critical path of 10h, dates from dateutil, the rich table; 9 pytest tests. 13 distributions in all.
S3
11 results and the summary line; 31 checks in its own tests.
S4
Valid and invalid rows, the top two customers, ISO weeks, a total of 728.50; 14 asserts. In round 2 the newest commander needed Node 22, so the AI picked 13.1.0 for Node 18.
Screens from the scored runs 4
S1: the React budget app running in the G-Code Lite preview on iPad
S1 React budget app
S2: the Python planner's output in the G-Code Lite terminal
S2 Python planner python main.py
S3: the C++ calculator built and run in the G-Code Lite terminal
S3 C++ calculator sh build.sh && ./calc
S4: the Node.js order report in the G-Code Lite terminal
S4 Node.js order report node index.js report --top 2
A re-check without a new request

In round 2 the S1 test stopped on its own mistake: it took the search box for the Description field. After three fixes to the test, the same project was checked again. No request was sent, and round 1's two failures ($0.0273) stay on the record: $0.1782 for the whole batch.

Stress, doubled. All four in one run.

Twice the packages, files, features and checks, on the same $23. The batch passes only if all four pass in the same run; an app fix means running all four again.

The doubled stress batch, task by task and round by round
TaskRound 1Round 2Round 3, scored
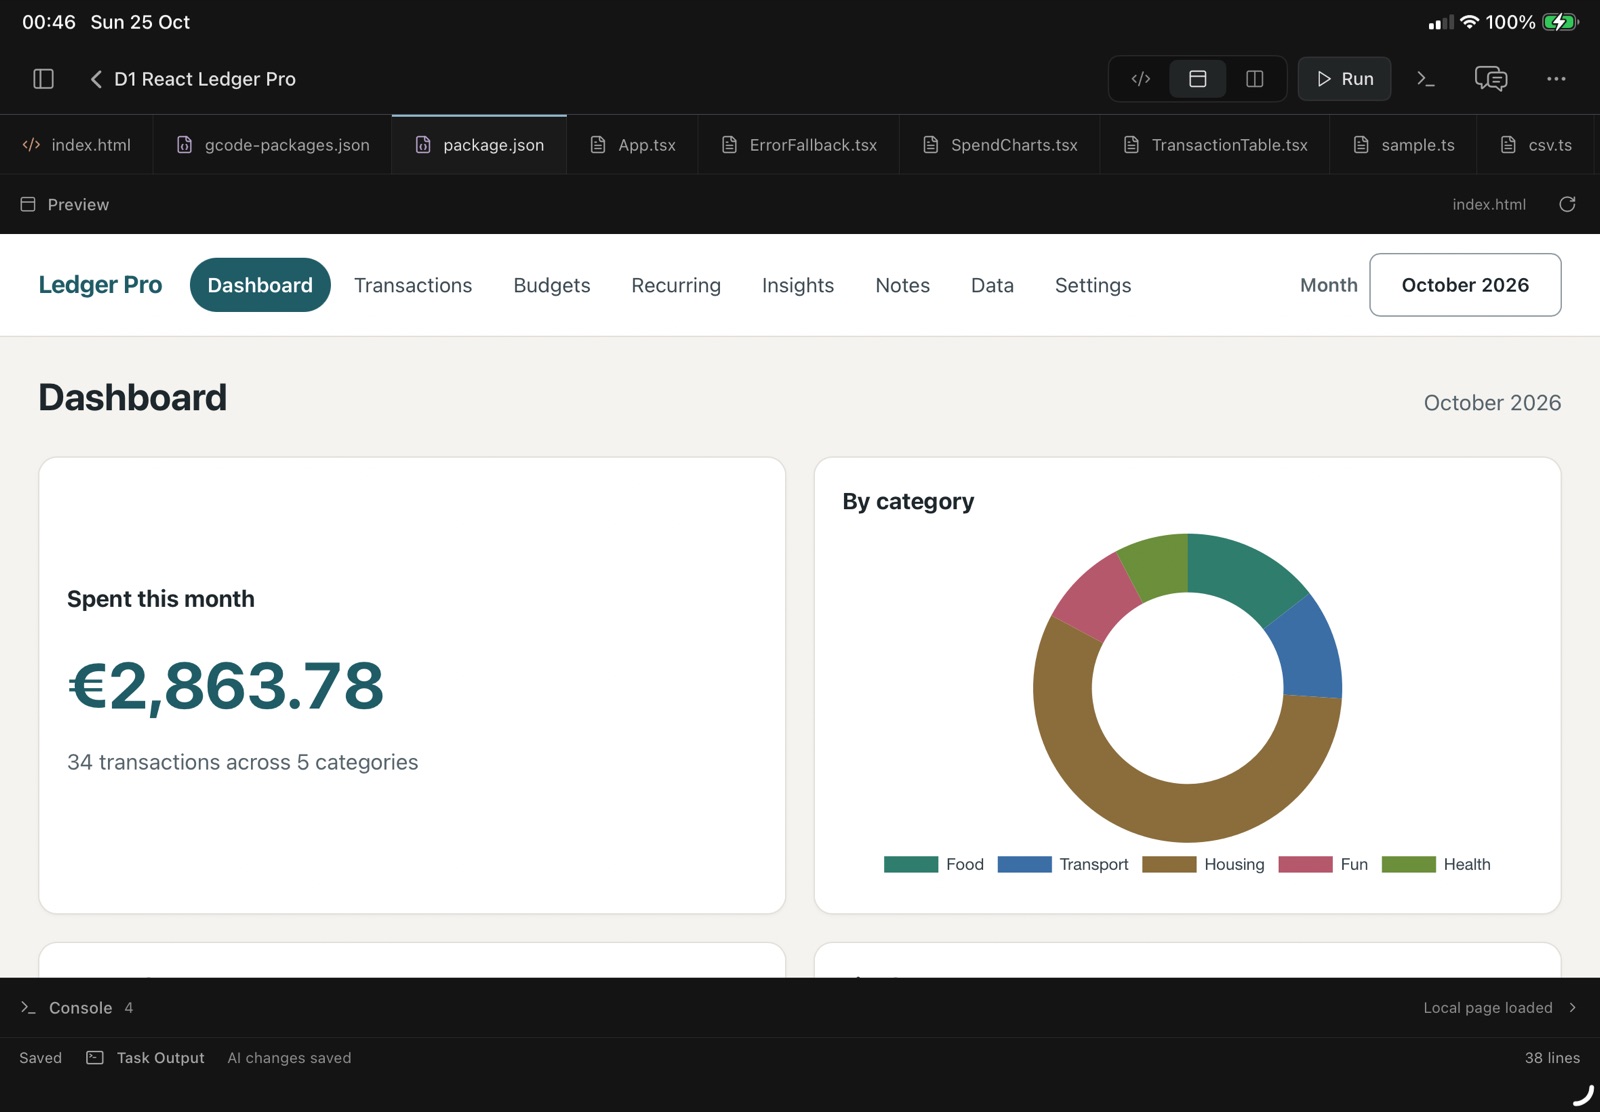
D1 React “Ledger Pro”32 npm packages, eight pages Failed $0.4619rrule 2.8.1 was called a damaged download, so there was no build. Stopped $0.0079The API key expired (HTTP 401). Passed $0.4595 · 39:00
D2 Python planner XL12 PyPI packages, four commands Failed $0.0325Every line matched, but pytest crashed with INTERNALERROR. Passed $0.0265 Passed $0.0264 · 7:16
D3 C++ interpreterAbout 20 files, 4 of them tests Passed $0.0586 Passed $0.0515 Passed $0.1352 · 11:50
D4 Node.js order analytics14 npm packages, four commands Passed $0.0436 Passed $0.0461 Passed $0.0419 · 13:30
Per round2/4 · $0.59663/4 · $0.13204/4 · $0.6630

$1.3916 over all three rounds, of the $23. After round 2, TN Lee saved a new key and all four ran again.

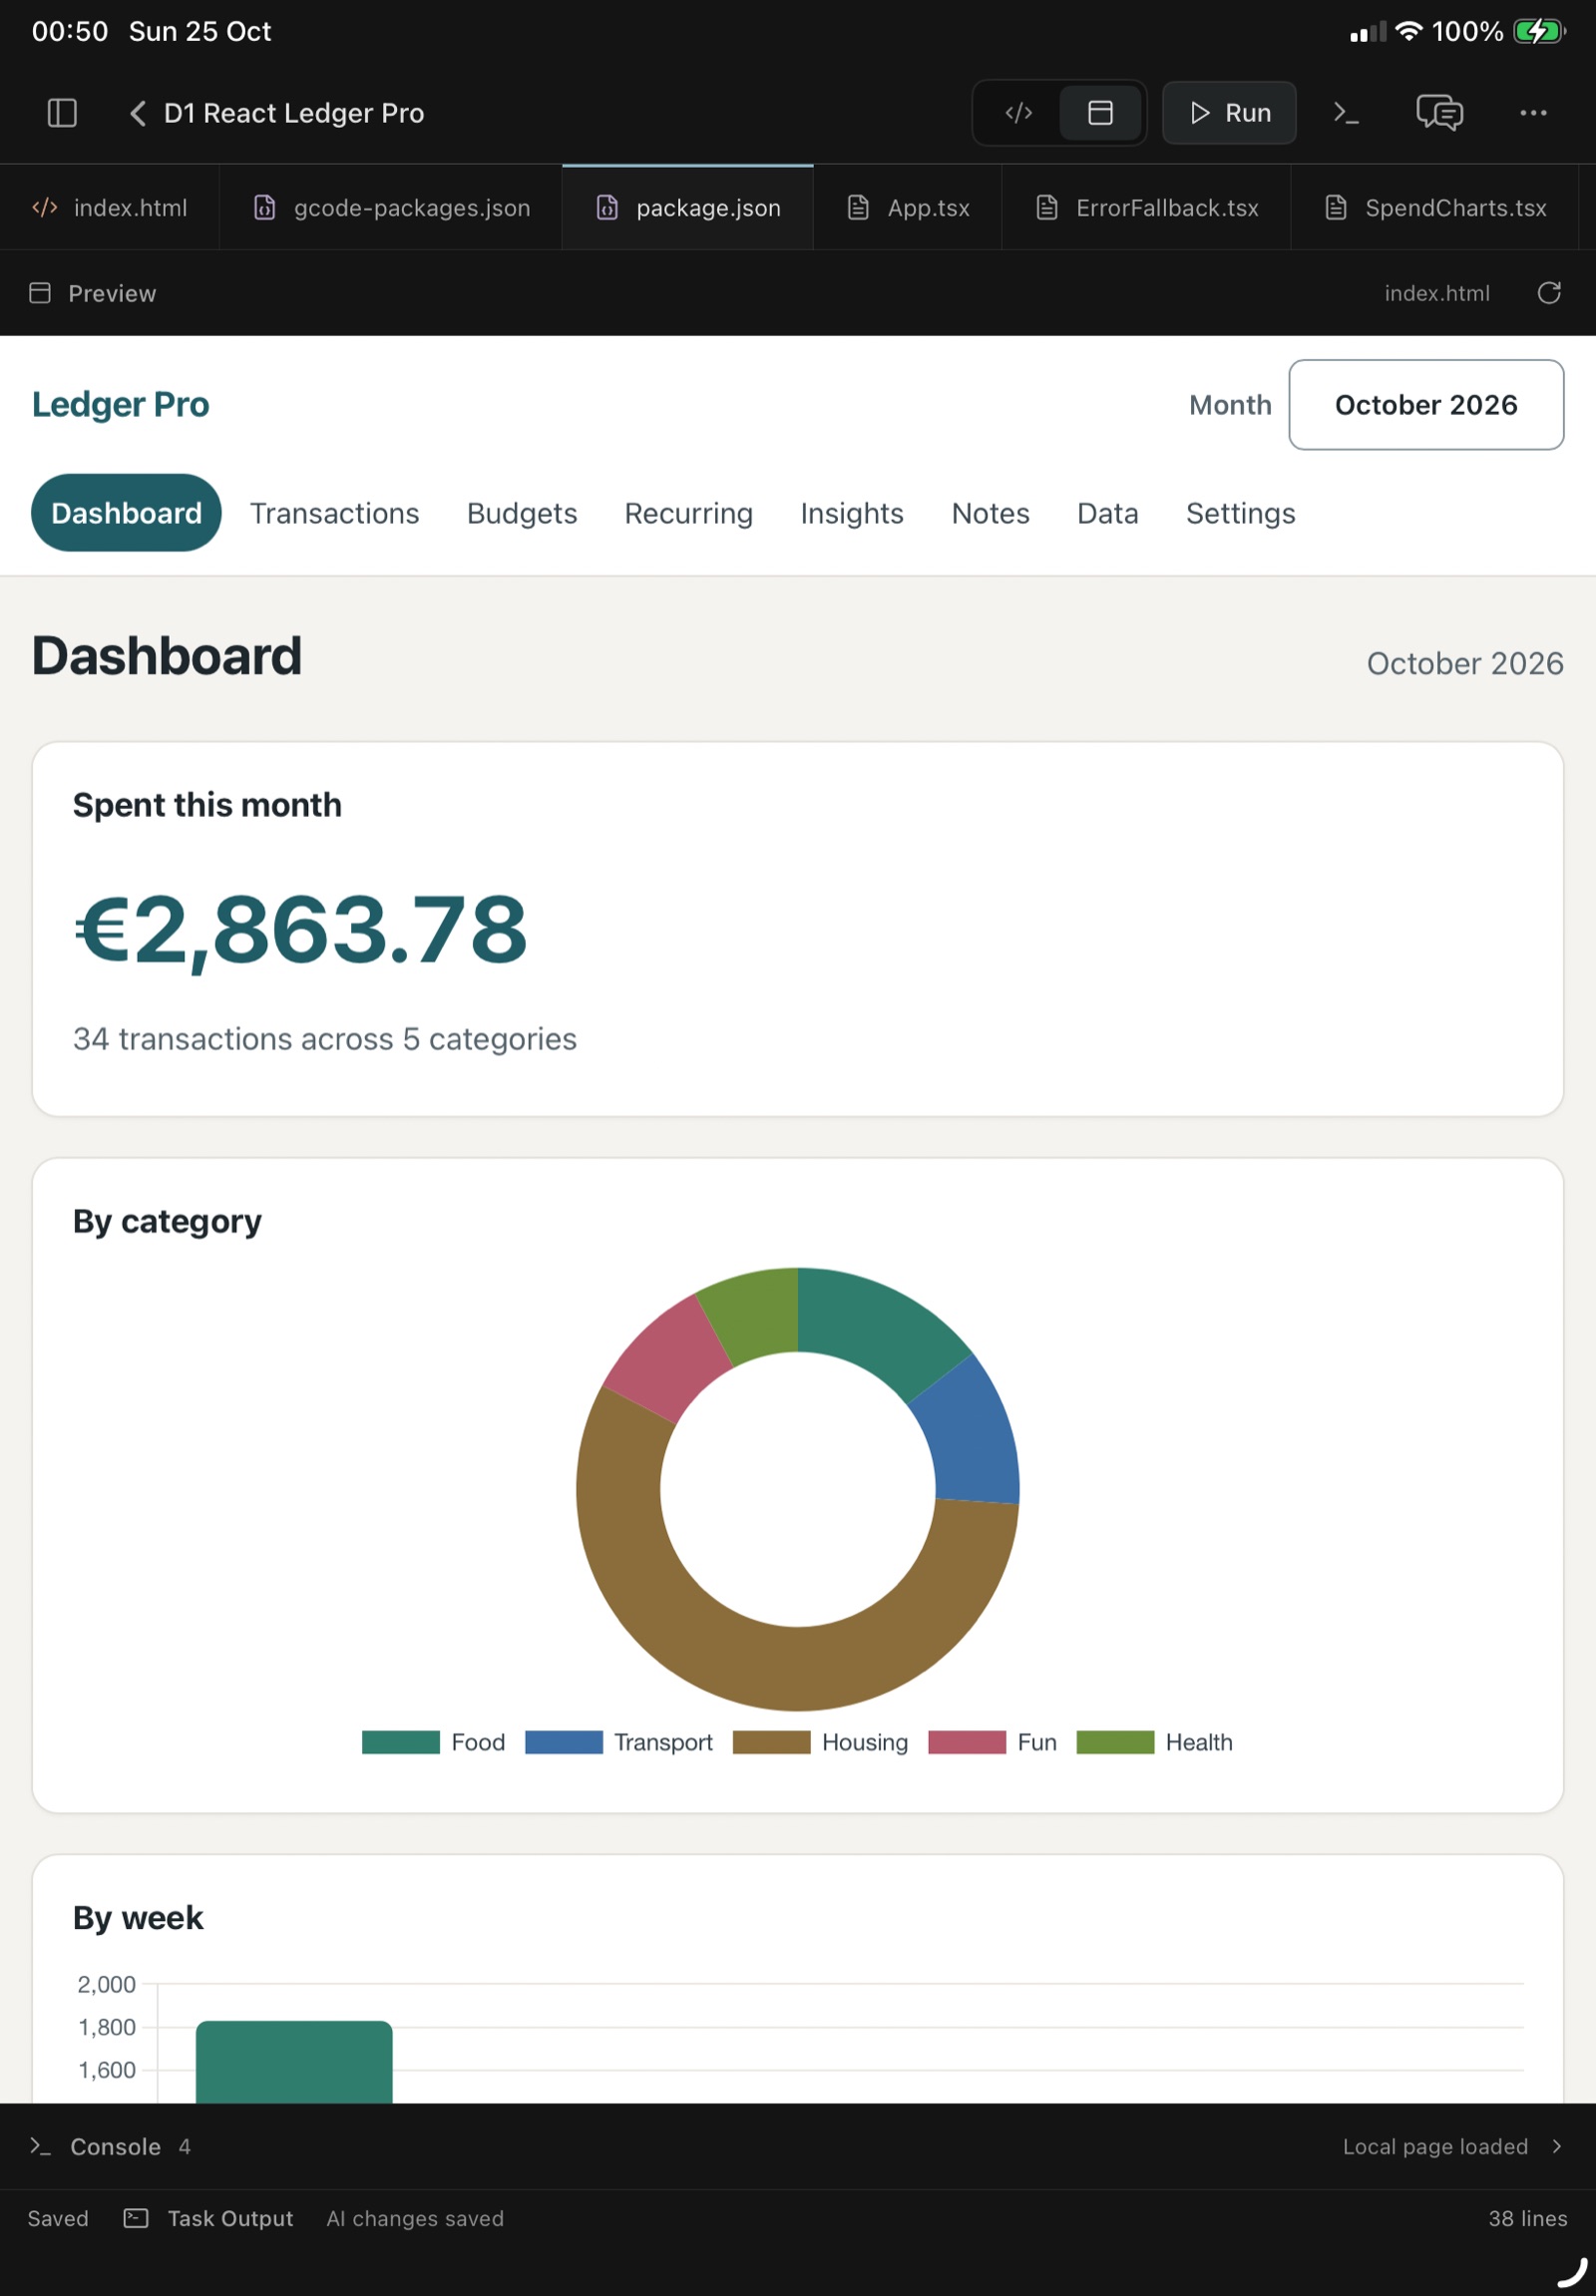
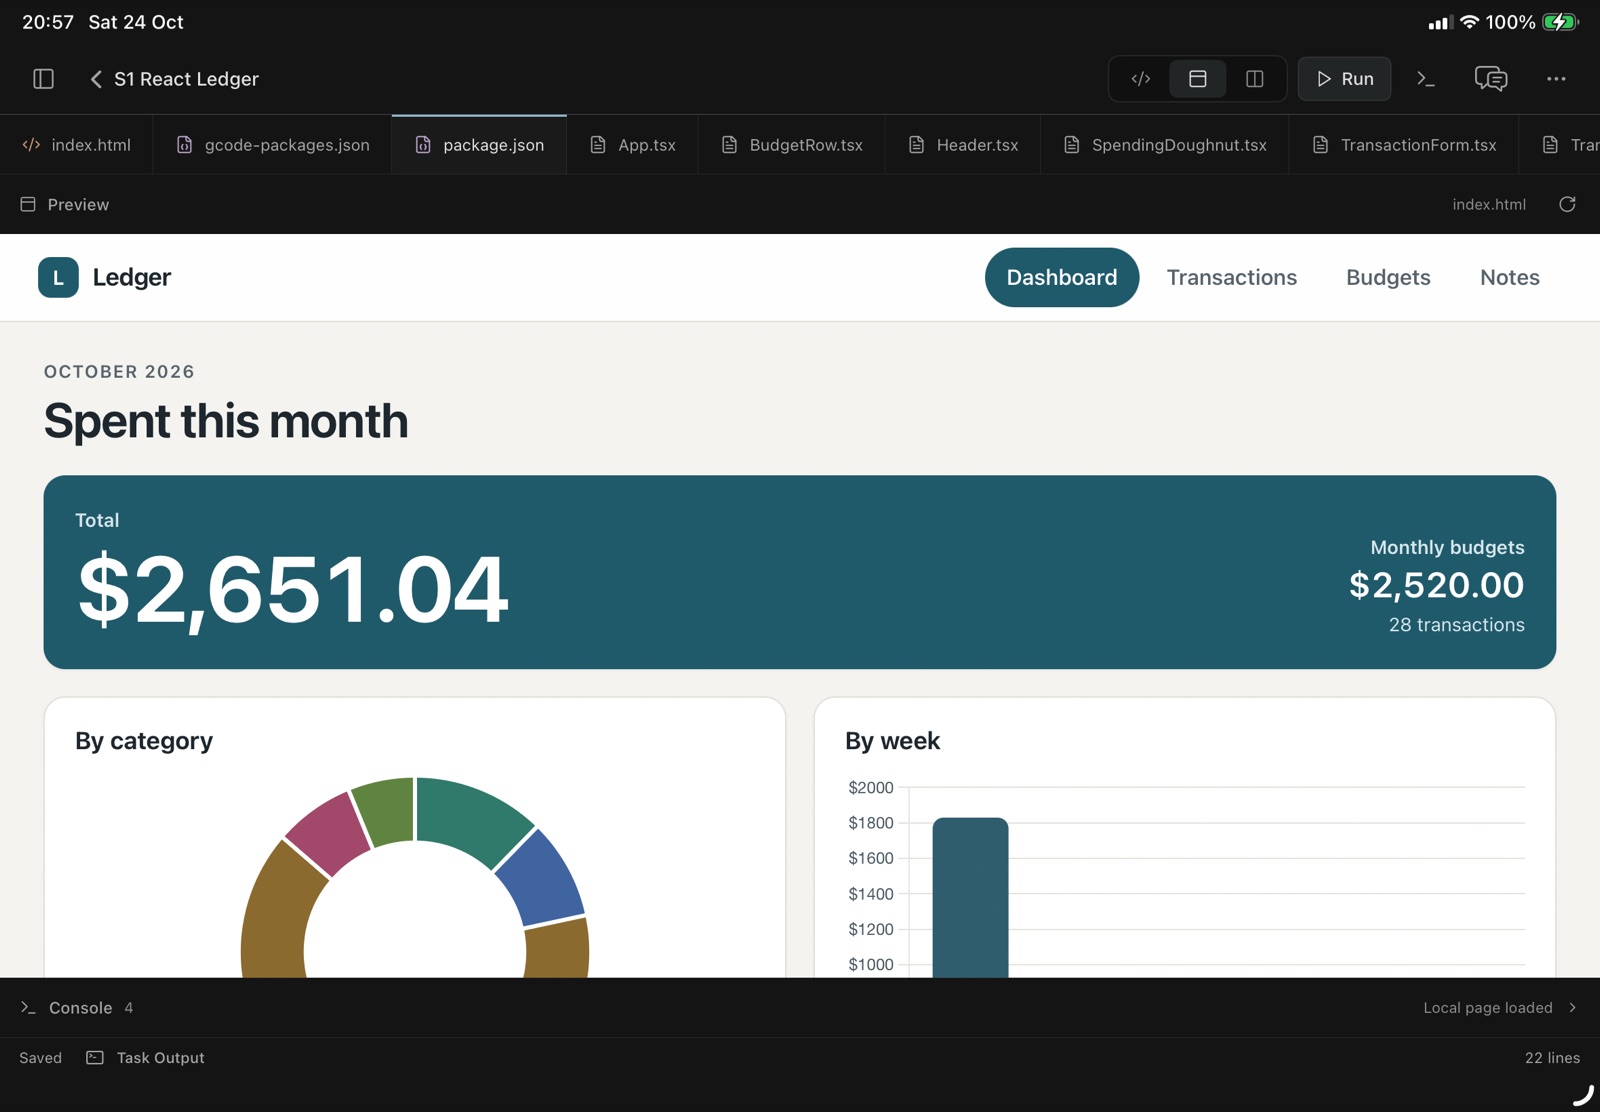
D1: the Ledger Pro dashboard with this month's spending and a category chart, in the G-Code Lite preview
D1 React on 32 npm packages
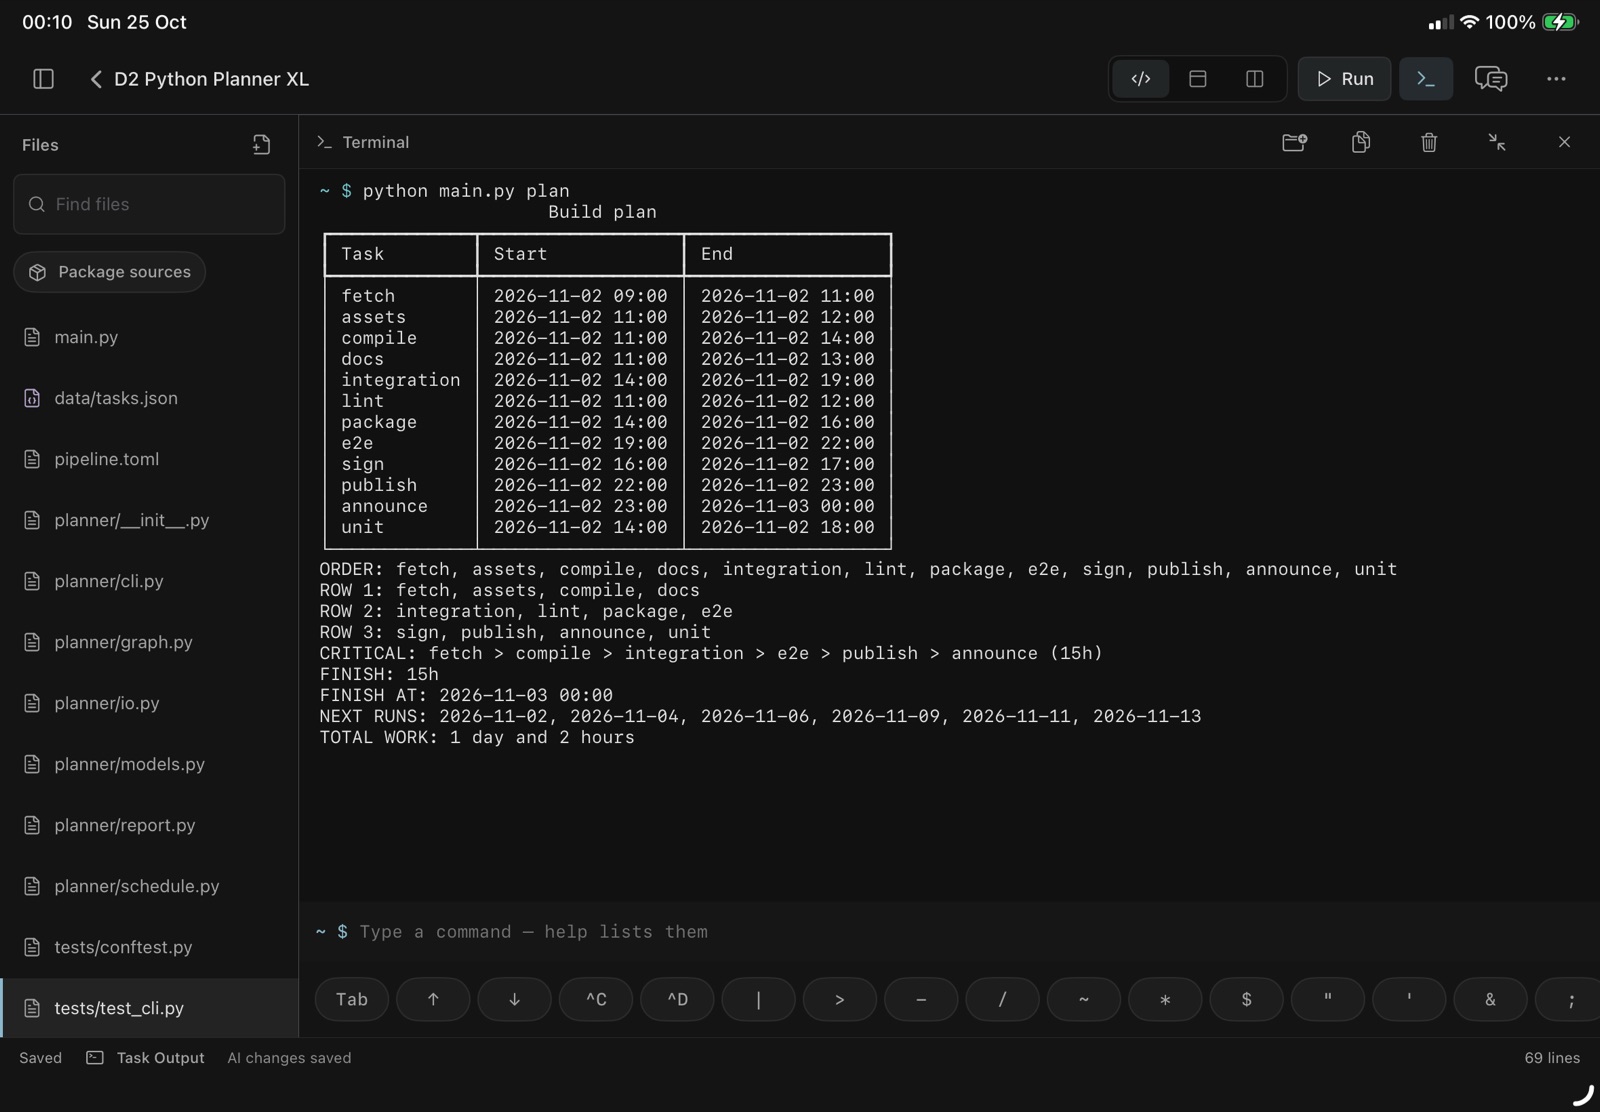
D2: the build plan table and its critical path in the G-Code Lite terminal
D2 Python on 12 PyPI packages
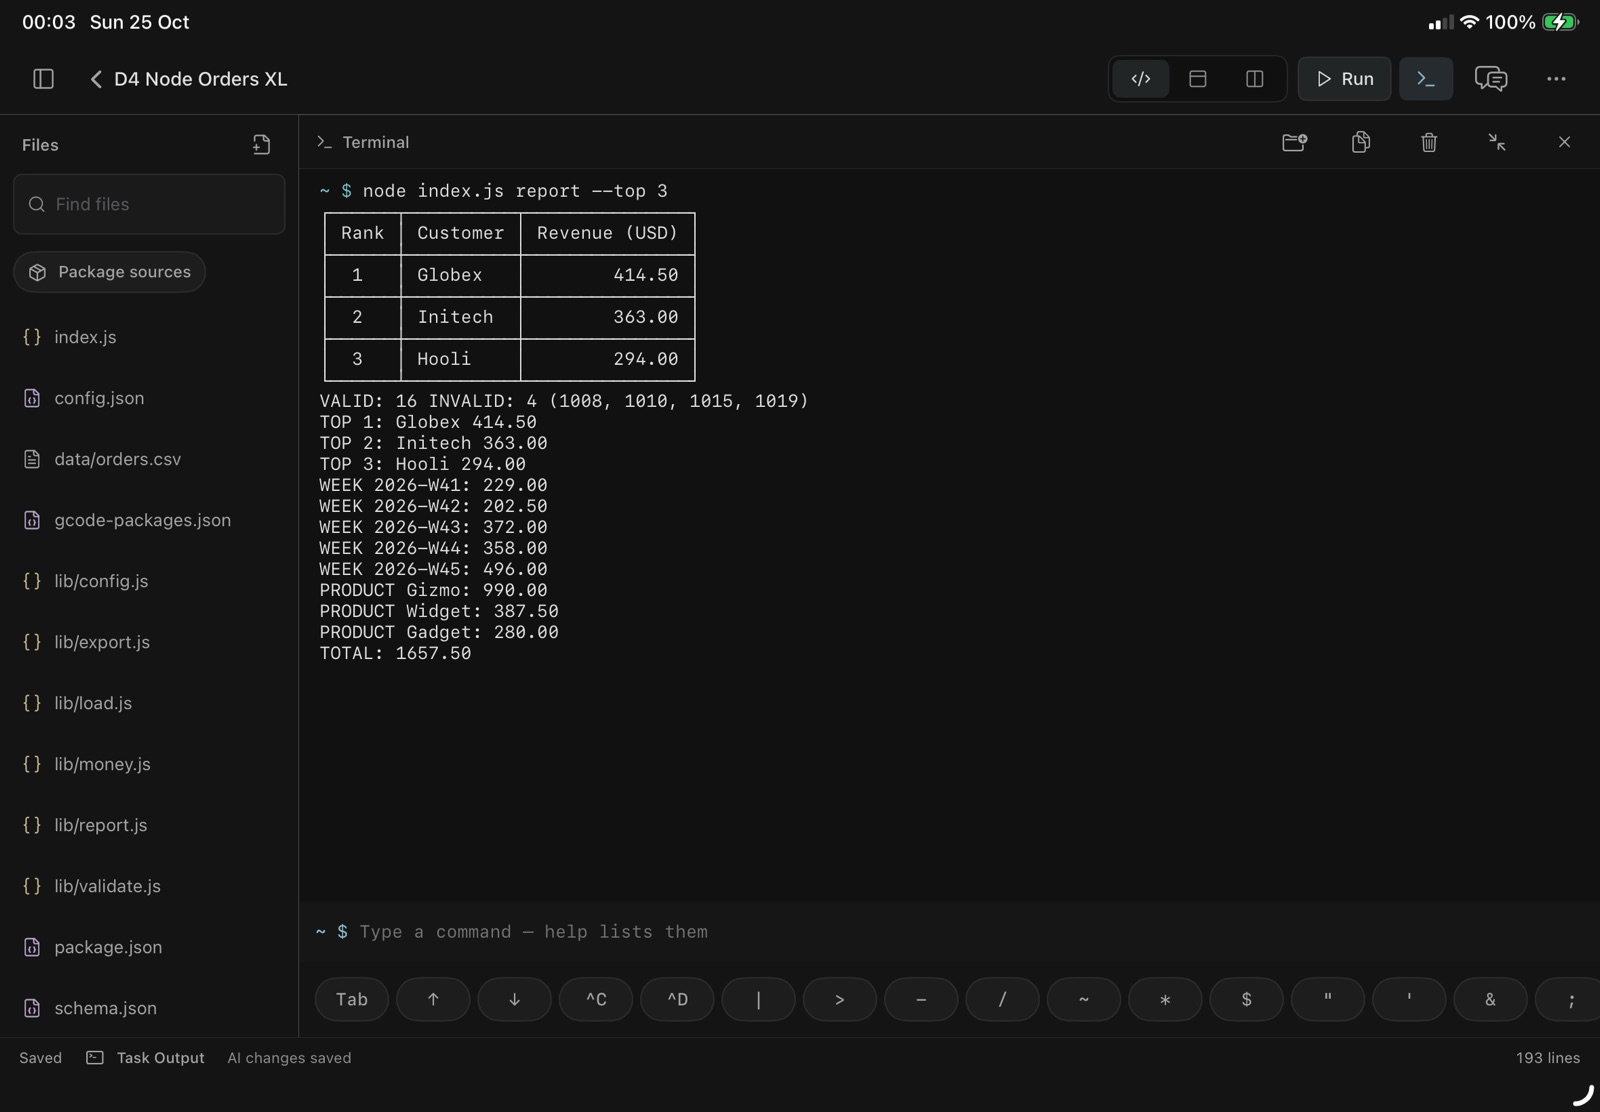
D4: the order analytics report in the G-Code Lite terminal
D4 Node.js on 14 npm packages
Four fixes, in build 25
Room for big dependency sets
Raised before round 1: 6,000 files per install (was 3,001) and 10,000 per project (was 4,096). The two sets came to 3,889 and 3,652 package files. On the simulator, a 9,217-file project backed up and restored with every file.
rrule installs
Its archive lists the package folder itself; that entry is skipped now. Anything else outside the package is still refused.
pytest runs whole
The embedded Python's terminal streams report the process's own file descriptors, so faulthandler works.
Errors that say what's wrong
In round 1 the app refused the AI's stage_changes input four times with only "Check your settings and try again". It now names the field and the shape it expects.
What each task was checked against
D1
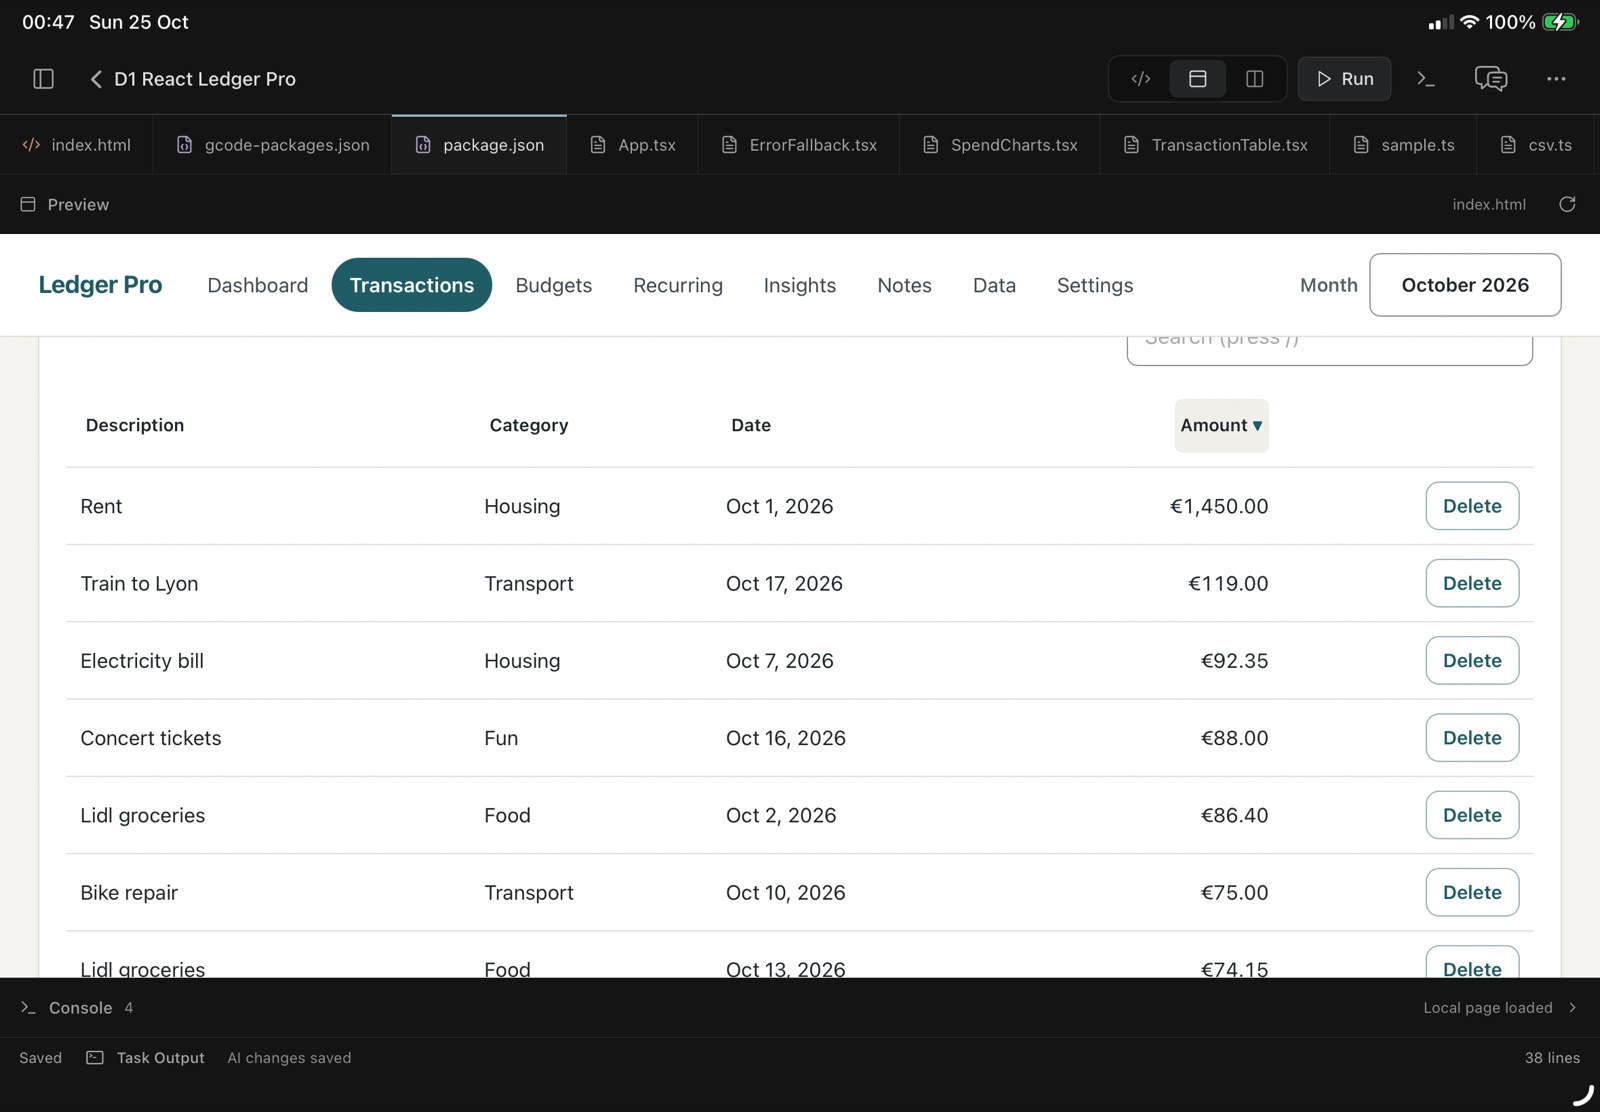
All eight pages, search, sorting, validation, add and delete with notices, an IBAN check, a QR code, the console. 45 packages with their dependencies, 3,889 files.
D2
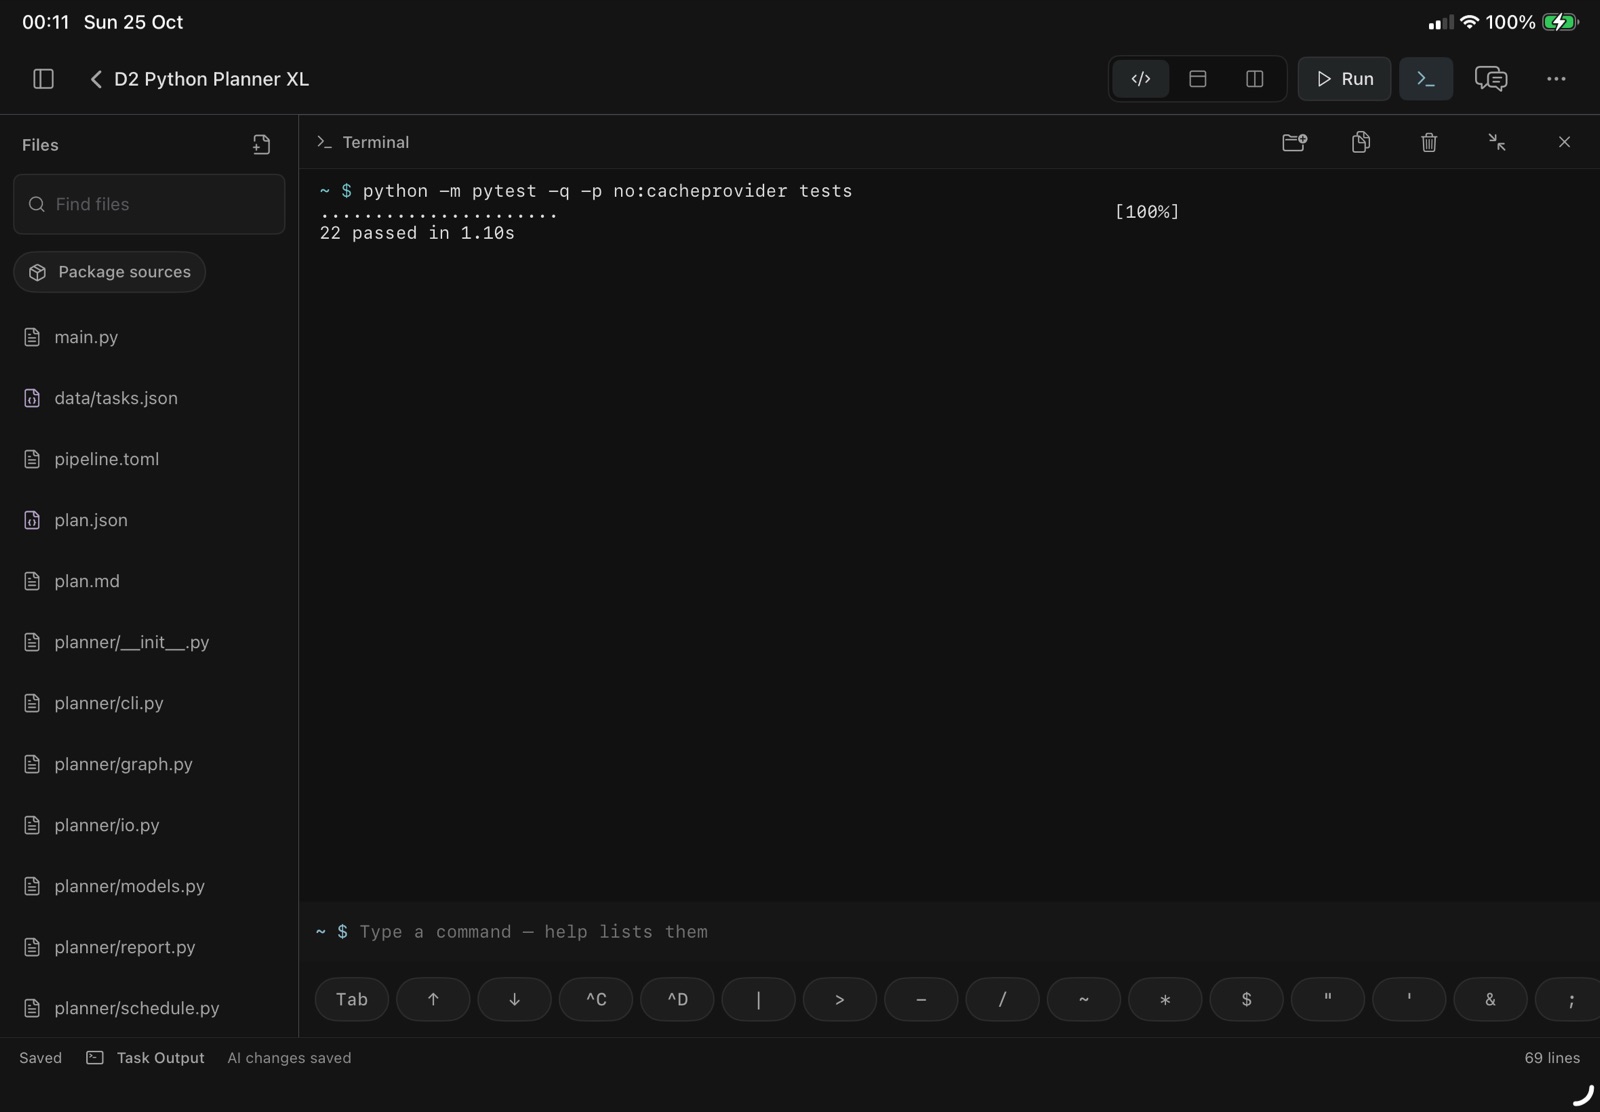
Run order, a 15h critical path, the finish time, six run dates, waves, schedules for one and two workers, exports; 22 pytest tests. 21 distributions, 12 tasks.
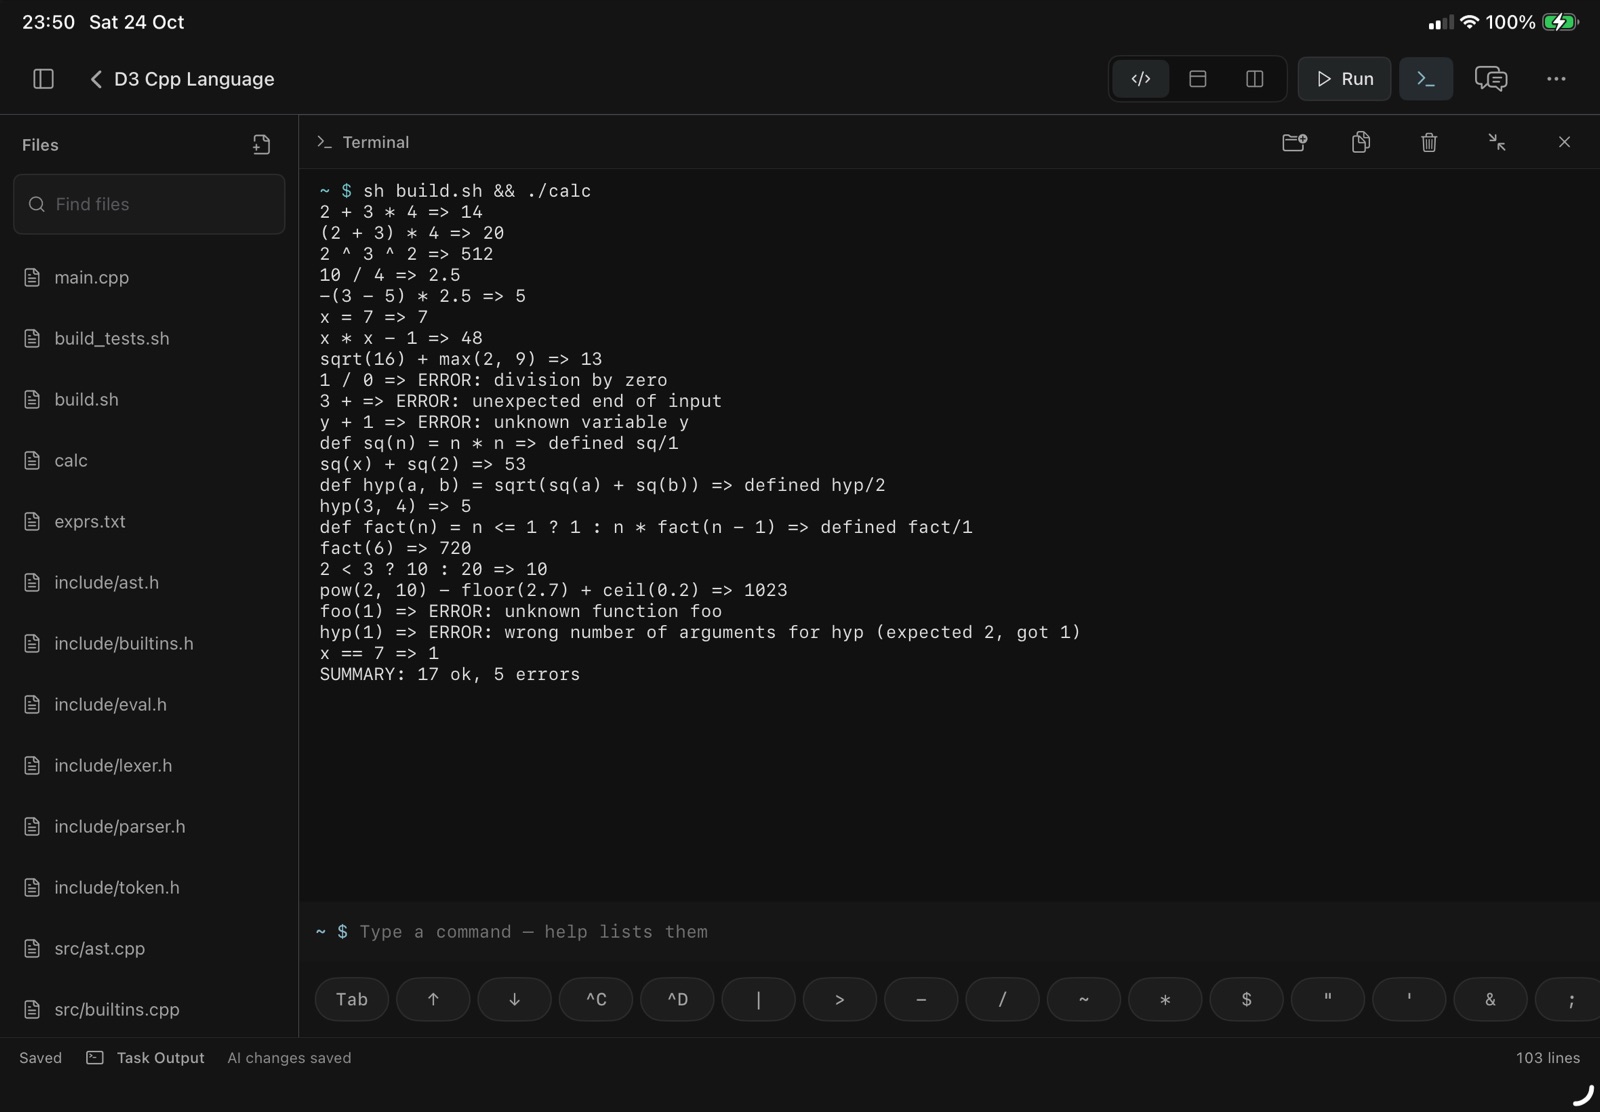
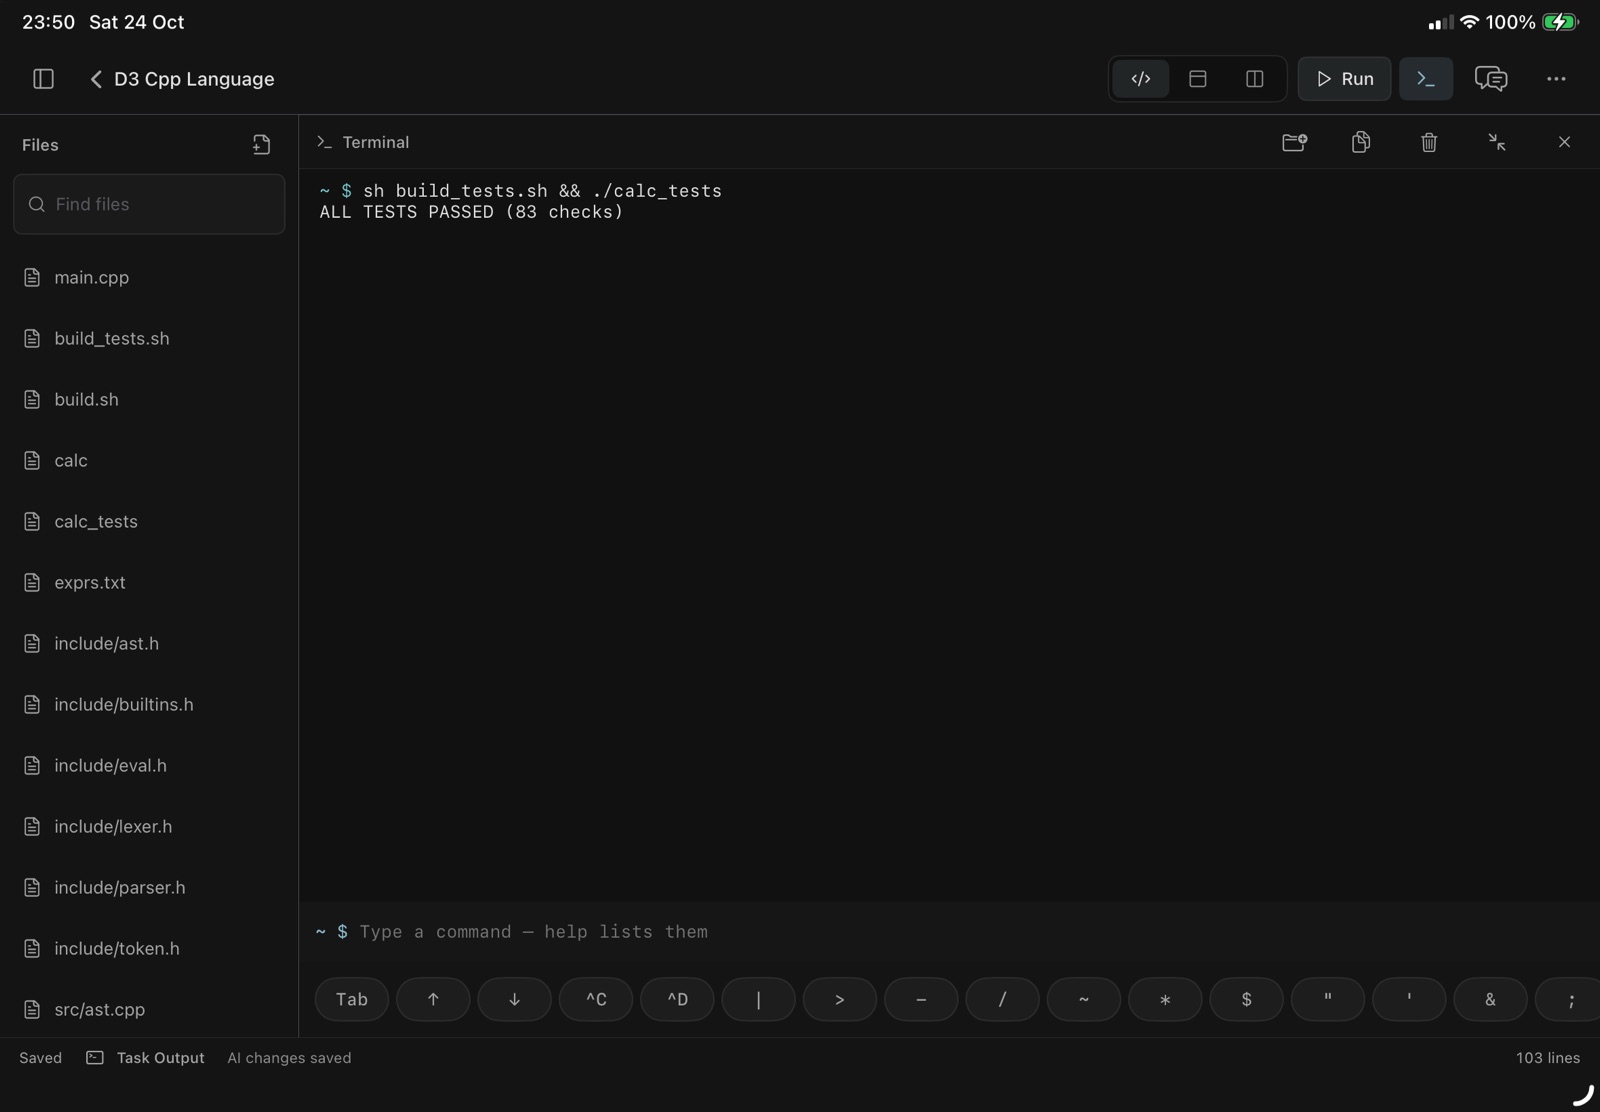
D3
22 results, from user functions and recursion to five kinds of error; 83 checks in its own tests. Six modules and a main file.
D4
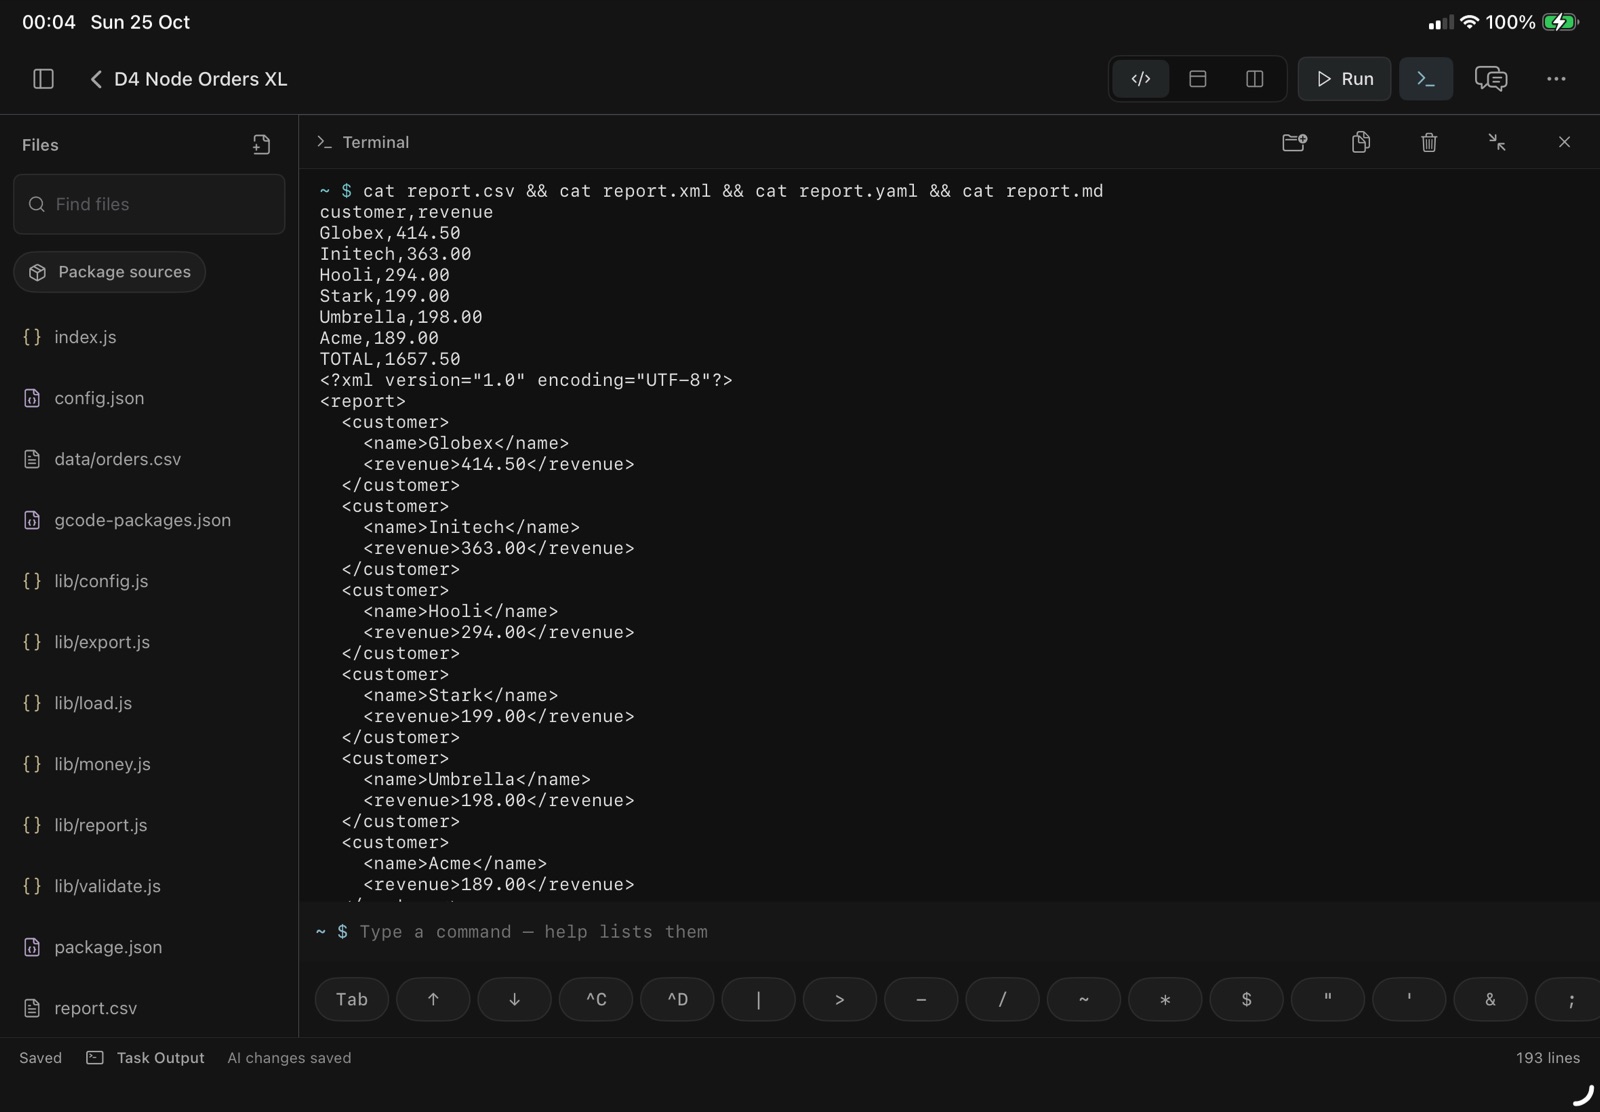
16 valid and 4 invalid rows, the top three, five ISO weeks, a total of 1657.50, fuzzy search, four export formats; 23 asserts. 35 packages with their dependencies, 3,652 files.
All screens from round 3 13
D1: the Ledger Pro dashboard with this month's spending and a category chart, in the G-Code Lite preview
D1 Ledger Pro
D1: the Ledger Pro dashboard in portrait
D1 In portrait
D1: the transactions table sorted by amount, largest first
D1 Sorted by amount
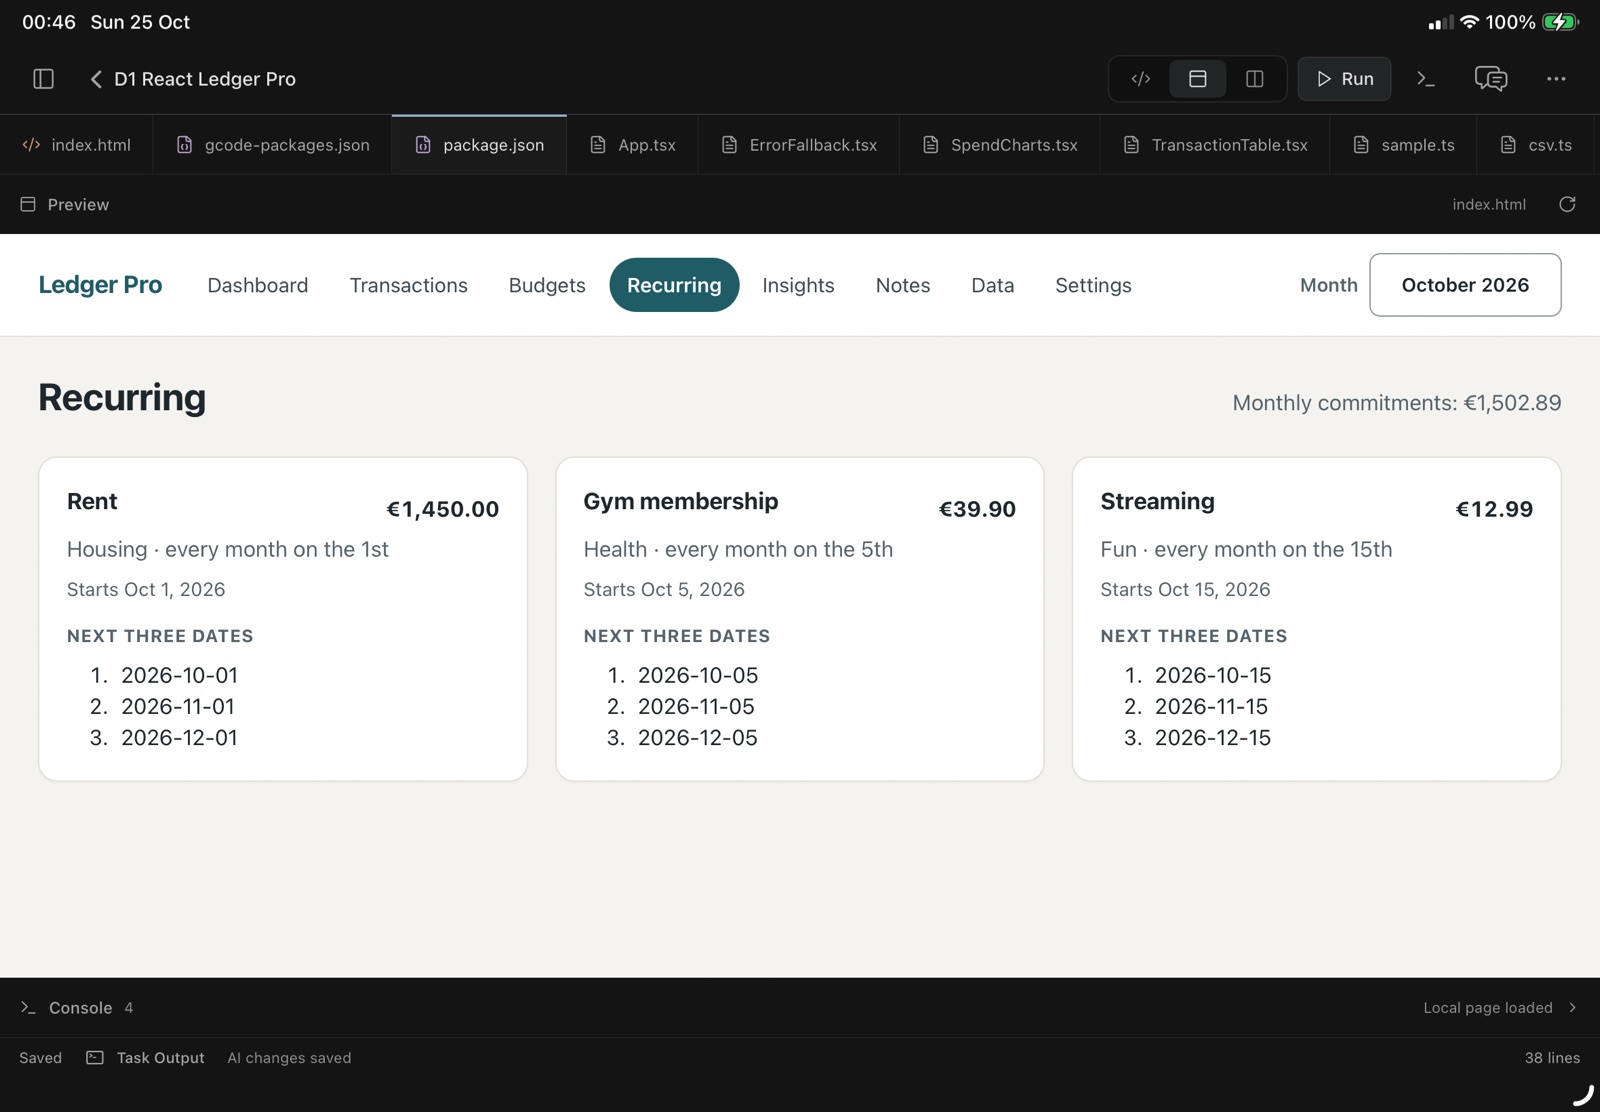
D1: recurring bills with their next dates
D1 Recurring bills from rrule
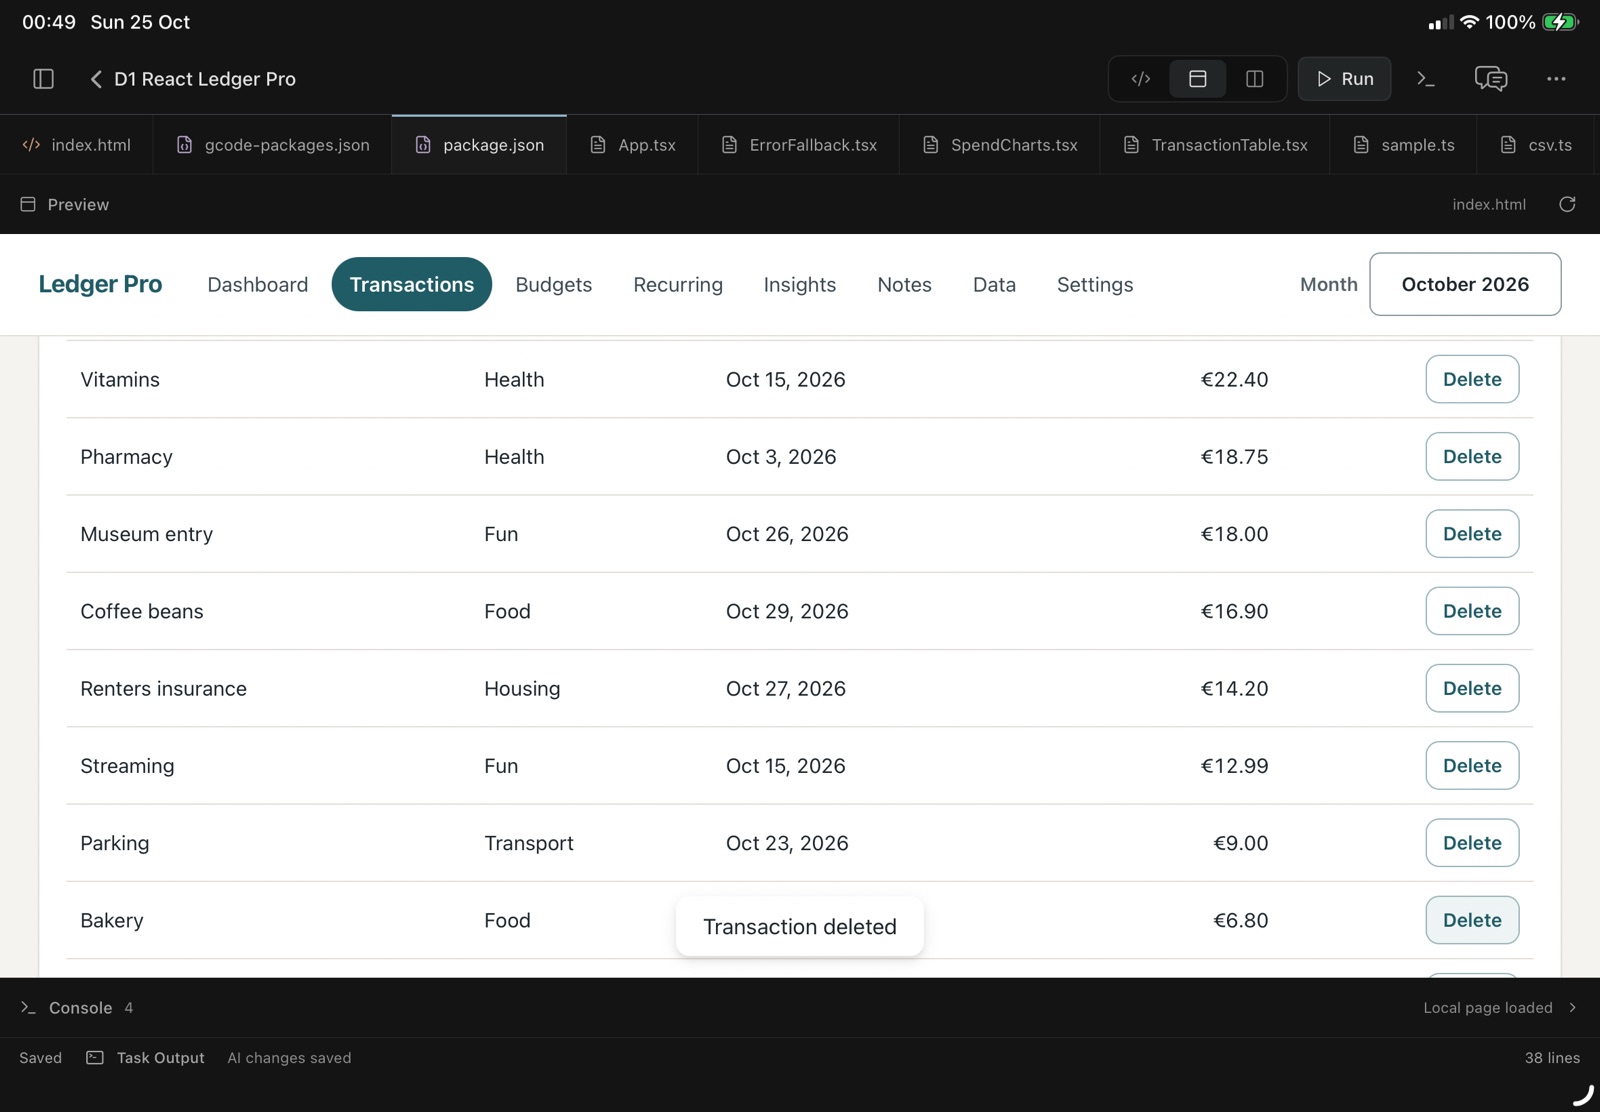
D1: a deleted transaction with its notice
D1 A row deleted
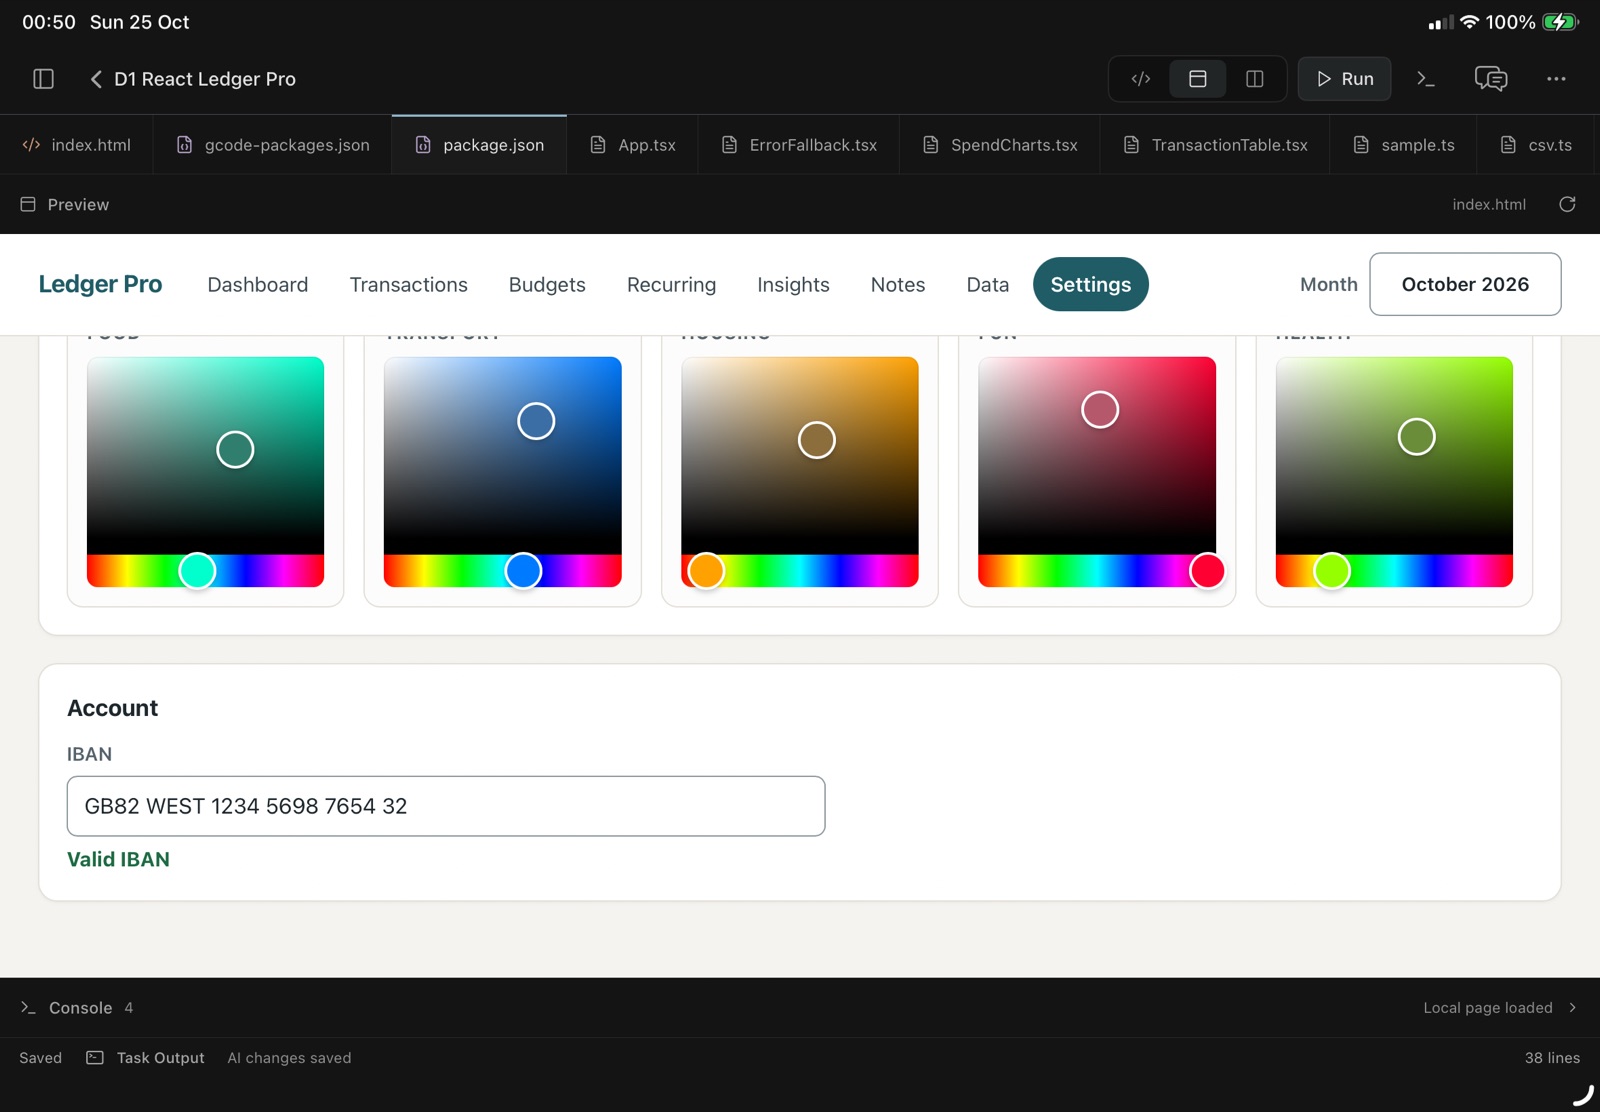
D1: category colour pickers and a valid IBAN check on the settings page
D1 An IBAN check
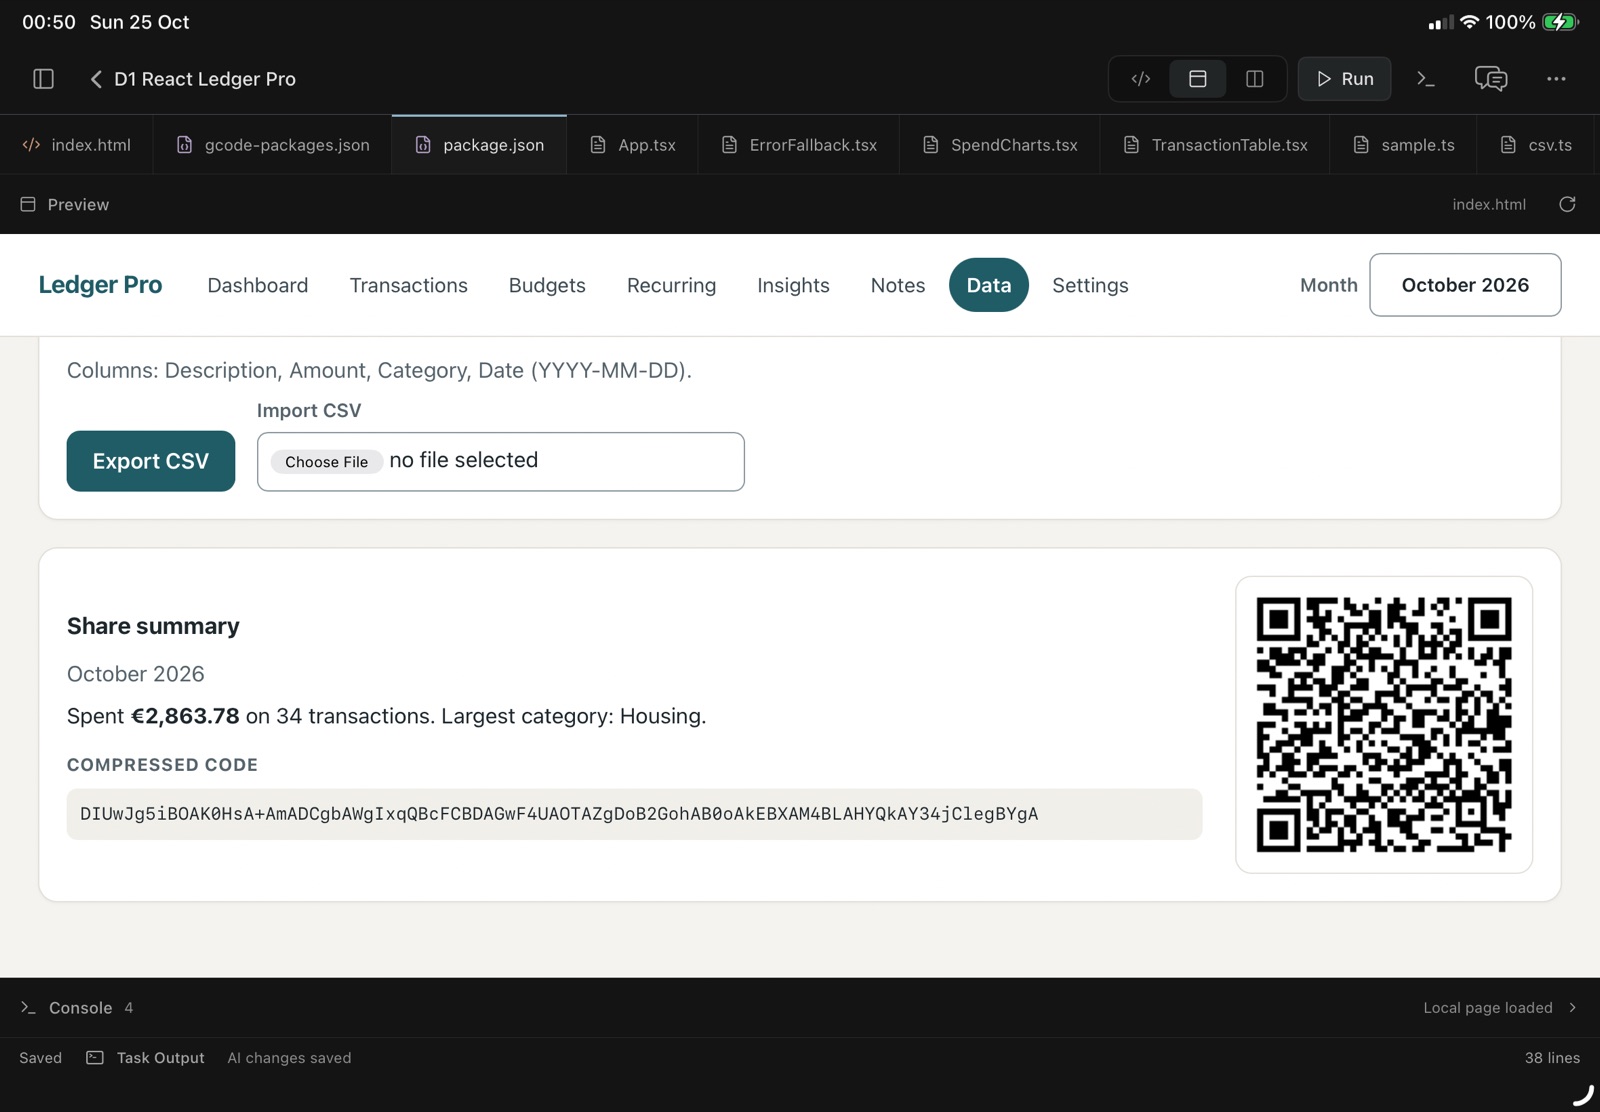
D1: the data page with CSV export and a QR code of the summary
D1 CSV export and a QR code
D2: the build plan table and its critical path in the G-Code Lite terminal
D2 The plan python main.py plan
D2: 22 pytest tests passing in the G-Code Lite terminal
D2 22 pytest tests pass
D3: the C++ interpreter's 22 results and summary in the G-Code Lite terminal
D3 The interpreter ./calc
D3: the interpreter's own test program passing 83 checks
D3 83 checks ./calc_tests
D4: the order analytics report in the G-Code Lite terminal
D4 The report --top 3
D4: CSV, XML, YAML and Markdown exports printed in the terminal
D4 Four export formats

* Tasks built and components tested using the Claude API: Claude Haiku 5.5 for the small apps, the runtime tasks and both stress batches; Claude Opus 5.5 for the five-page sites and Project PRIDE. The businesses, people and figures inside the AI-built sites were invented by the model.

The fine print.

What these runs don't show, and how they were counted.

Not shown

  • Anyone else's projects. Every run here was ours, on one iPad Air.
  • Hundreds of source files, or packages with native code.
  • Visual quality in the stress batches. It wasn't scored.
  • Clicks inside Project PRIDE. Its search and forms were checked by reading the code.

Limits we hit

  • Node.js is 18, so the newest commander (it needs 22) is out.
  • pip installs pure-Python packages only; hypothesis gave way to tomlkit.
  • The AI can't install packages itself. You run pip in the terminal first.
  • 32 npm installs one at a time take about 15 minutes.

How we counted

  • Strictly: a console error, a missing package or a failed build check is a failure.
  • By the test, against answers worked out on a Mac, never by the AI's own report.
  • Each task sent once. Failed rounds are shown here and not scored.
  • Settled API usage at Anthropic's list prices, on our own key. Held amounts are named, not added.
  • Not counted: PRIDE's voided first attempt (8 of 10 pages, $6.26) and interrupted site attempts.
  • A verified backup before and after every batch; the iPad's own projects stayed byte-identical.

Coming soon to iPad